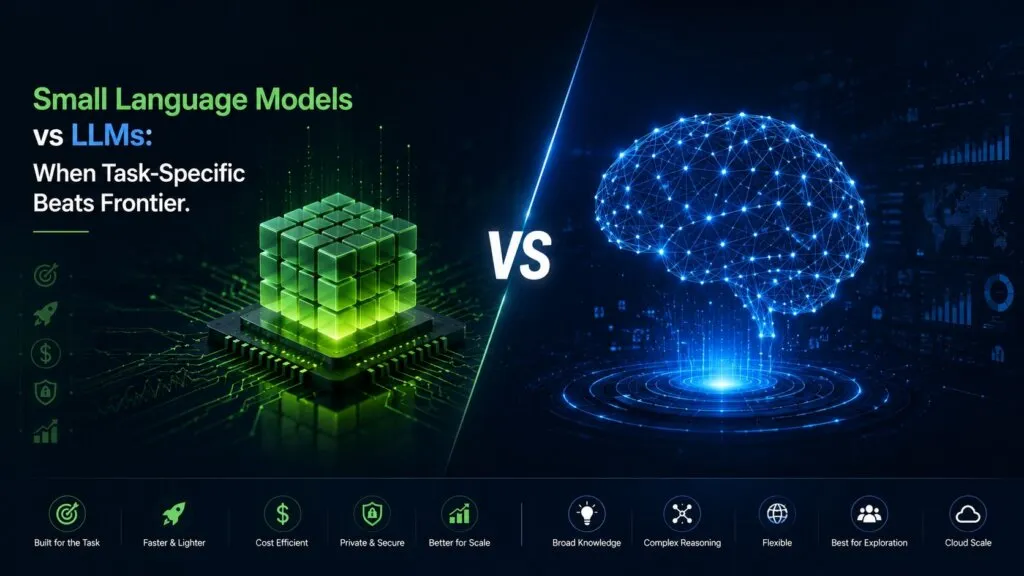
Small language models are forcing a useful rethink of an assumption that dominated enterprise AI strategy for years: that bigger is always better. That assumption made sense when frontier LLMs outperformed every alternative on almost every task. It makes less sense now. Fine-tuned small language models can match or exceed frontier models on the specific, well-defined tasks that make up much of real enterprise AI work.
They do it at a fraction of the inference cost and with better data privacy. Gartner has predicted that by 2027, organizations will use small, task-specific AI models three times more than general-purpose LLMs. That is a notable forecast for a firm that rarely overstates adoption timelines.
ICANIO works with enterprises in manufacturing, fintech, healthcare, retail and logistics on AI model selection. The SLM vs LLM question comes up in almost every engagement. The honest answer is that neither is universally better. The teams that get the most value treat it as an engineering decision, made per use case, based on cost, latency, data sensitivity and required performance.
Key Takeaways
- Small language models share the transformer architecture of LLMs; the difference is scale, not design.
- Four questions settle most SLM vs LLM decisions: task scope, data sensitivity, inference cost and latency.
- Fine-tuning an open foundation model with LoRA or QLoRA is far cheaper than training from scratch.
- Task-specific AI built on small language models often wins in manufacturing, finance and support.
- Hybrid architectures route routine work to SLMs and escalate complex queries to frontier LLMs.
What Are Small Language Models?
Small language models are transformer-based neural networks, usually with a few million to around seven billion parameters. They are designed to run efficiently on limited hardware, often without cloud dependency. The small language model entry on Wikipedia gives a good overview.
They use the same foundational architecture as frontier LLMs. The key difference is scale, not design philosophy. Microsoft's Phi family includes Phi-3 Mini at 3.8 billion parameters. Google's Gemma launched with a 2 billion parameter variant, and TinyLlama has 1.1 billion. Frontier models are far larger, often estimated in the hundreds of billions of parameters or more.
That scale difference drives hardware requirements, inference cost and deployment flexibility. It also shapes how much fine-tuning is needed to reach strong task performance.
Why "Small" Is a Moving Target
The word "small" is relative to the current frontier. It will keep shifting as hardware improves. For enterprise decisions, the parameter count matters less than what it implies:
- How much compute it takes to serve the model at scale.
- Whether it can run on-premises or at the edge without cloud infrastructure.
- How practical fine-tuning on proprietary data really is.
The SLM vs LLM Decision Framework
Most published SLM vs LLM comparisons list pros and cons and leave the decision to the reader. That is not much help for a team facing a specific architectural choice. Our team uses four questions instead. Answered honestly for one use case, they usually point to the right answer without a lengthy evaluation.
| Question | Favors SLM | Favors LLM |
|---|---|---|
| Task scope | Narrow, bounded | Open-ended |
| Data sensitivity | Regulated, private | Low risk |
| Volume and cost | High volume | Low volume |
| Latency | Real time, edge | Tolerant |
1. Is the Task Well-Defined and Bounded?
Small language models excel at specific tasks where inputs and outputs are constrained. Examples include document classification, intent detection, entity extraction, sentiment analysis and checks against a known rule set. In these tasks, "correct" is clearly determinable. Broad world knowledge is not required.
Frontier LLMs earn their premium on open-ended work. That includes complex reasoning, creative generation and multi-step analysis. If a task can be specified in a few sentences and scored against objective criteria, a fine-tuned small model is usually the right choice.
2. How Sensitive Is the Underlying Data?
Enterprise AI models handling regulated data, personal information or proprietary intelligence face a different risk environment. Data residency rules add further constraints. Sending this data to a third-party API means it leaves your infrastructure.
Legal and compliance teams in financial services and healthcare often cannot accept that exposure. Small language models running on-premises or in a private cloud keep sensitive data inside your controlled environment. That changes the compliance calculation significantly.
3. What Does Inference Cost at Scale?
Inference cost is one of the most concrete factors in the SLM vs LLM comparison. A 7 billion parameter open model served on your own GPUs typically costs a small fraction per token of a frontier API. The gap is often an order of magnitude or more, depending on hardware utilization and vendor pricing.
Consider a workflow processing hundreds of thousands of documents a day. That difference accumulates quickly. It can justify the fine-tuning investment needed to make a small model perform well. Always model your own volumes and current price lists before deciding.
4. How Much Does Latency Matter?
Some enterprise AI models sit inside real-time customer workflows, transaction processing or edge environments. Their latency budgets are tight. A small model running locally on edge hardware can respond in milliseconds.
The same query sent to a frontier API needs a network round trip to a third-party data center. That adds latency and an availability dependency. Many production use cases cannot tolerate either.
Fine-Tuning Small Language Models: The Build Path
A common misconception is that deploying small language models means building one from scratch. In practice, enterprise deployments almost always start from an existing open foundation model. Options include Phi-3, Gemma, Llama 3 and Mistral.
Teams then apply fine-tuning to adapt the model to a domain and task. The investment is far smaller than training from zero, in both data and compute.
How Fine-Tuning Works for Enterprise Use Cases
Fine-tuning trains the foundation model on curated examples of the production task. A compliance model learns from historical compliance documents and labeled outcomes. An insurance classifier learns from the document types that company actually processes.
Dataset quality matters more than size. A well-labeled, representative set of a few thousand examples often beats a poorly labeled set of tens of thousands. Our team recommends investing early in labeling guidelines and review.
LoRA and QLoRA
Parameter-efficient methods make this practical. LoRA trains small low-rank adapter matrices instead of all model weights. QLoRA adds quantization to cut memory further. Libraries such as Hugging Face PEFT implement both.
Together they let teams without large GPU clusters fine-tune capable small language models on standard cloud infrastructure. We treat this pipeline as production engineering, not a research experiment: dataset preparation, training, evaluation and deployment, all automated.
Where Task-Specific AI Outperforms Frontier Models
The gap between small language models and frontier LLMs on domain tasks has narrowed considerably in recent years. For task-specific AI in well-defined domains, fine-tuned small models can now match or beat frontier performance. They also deliver lower latency, lower cost and better privacy at the same time. Results vary by task, so always benchmark on your own data.
Manufacturing and Quality Inspection
Defect classification and anomaly detection in manufacturing are a natural fit. The input space is well-defined. Ground truth labels exist in historical quality data. General world knowledge is not needed.
A model fine-tuned on a manufacturer's own defect taxonomy tends to outperform a general frontier model on those defect types. It can also run at edge speed on production line hardware, close to IoT sensors and machine learning pipelines. Our post on AI defect detection covers this use case.
Financial Services Compliance
Compliance checks, document classification and entity extraction are bounded, well-specified tasks. This is where task-specific AI delivers its strongest advantage. A model trained on a bank's rule set, document formats and case history can work with higher precision than a frontier model given general instructions.
It also keeps customer data inside the institution's own infrastructure. For regulated firms, that alone can decide the SLM vs LLM question.
Retail and Customer Support
Intent classification and routing in retail support is high volume and cost sensitive. Here the cost gap becomes very visible. A well-tuned small model can handle intent detection and simple queries. Only the complex or ambiguous ones go to a more expensive frontier model.
The Hybrid Architecture Approach
The SLM vs LLM framing helps explain trade-offs. As an architectural rule, though, it can mislead. The most effective enterprise AI models architectures often combine both.
Small language models handle high-volume, well-defined tasks where cost and latency dominate. Frontier LLMs handle open-ended tasks where broad knowledge and reasoning earn their cost. This resembles microservices in software development, where specialized services outperform a single monolith.
How We Design a Hybrid Portfolio
Our process follows a simple sequence:
- Map every AI task across the target workflow.
- Score each task on specificity, data sensitivity, latency and volume.
- Assign each task to a model tier.
- Add a router that escalates low-confidence answers to the larger model.
The result is usually a portfolio of fine-tuned small language models for high-frequency domain work. A frontier LLM or retrieval augmented generation assistant covers tasks that genuinely need that capability. For a deeper comparison of adaptation strategies, see RAG vs fine-tuning.
Keeping Small Language Models Accurate Over Time
A fine-tuned model that performs well at launch can degrade quietly. Task-specific AI tends to fail confidently within its domain rather than hallucinating outside it. That makes problems less obvious.
Keeping small language models accurate takes the same MLOps discipline as any production AI system:
- Monitor performance against a representative evaluation set.
- Track accuracy drift as the business domain evolves.
- Retrain on fresh data when performance drops below the agreed threshold.
Why Regulated Industries Need Extra Care
This discipline matters most in regulated industries. A compliance model trained on last year's rules can become a liability rather than a safeguard. Our team treats monitoring and retraining as a standing part of every fine-tuned model engagement. Catching drift early is cheaper and less disruptive than reacting after operations teams notice. Our guide on AI project failure after launch explains the MLOps controls involved.
Knowledge Distillation as an Alternative
Sometimes standard fine-tuning does not reach the quality a complex task needs. Knowledge distillation offers another path. A large frontier model generates high-quality labeled examples. A much smaller model is then trained to replicate that behavior on the specific task.
The result inherits targeted capability from the frontier model. It keeps the cost, latency and deployment advantages of a smaller architecture. This works well when ground truth data is scarce but a frontier model can reliably produce labels. Always check license terms before using one model's outputs to train another.
How to Evaluate Small Language Models Before Production
Choosing between candidate models should never rest on public leaderboards alone. Those benchmarks measure general ability, not your task. Build a private evaluation set instead.
A practical evaluation plan for small language models includes:
- Collect a few hundred real, anonymized examples from the target workflow.
- Label them carefully, with a second reviewer for disputed cases.
- Score each candidate on accuracy, latency and cost per thousand requests.
- Test edge cases, adversarial inputs and out-of-scope questions.
- Compare results against a frontier model baseline on the same set.
Keep the evaluation set separate from training data, or the scores will look better than reality. Rerun it after every retraining cycle so regressions surface before release. Our guide to LLM evaluation before deployment shows how to automate this as a release gate. The same gate works for small language models and frontier LLMs, which keeps comparisons fair.
Where ICANIO Fits in Enterprise AI Model Selection
ICANIO's Data and AI services cover the full spectrum of enterprise AI models. That ranges from fine-tuned small language models for high-volume tasks to frontier LLM integration for complex reasoning. We treat model selection as an engineering decision rather than a default.
Our teams combine data engineering, application development, DevOps, cloud engineering and MLOps. Turning foundation models into production task-specific AI is as much a data engineering discipline as a modeling one. The ongoing retraining and monitoring that keep models accurate matter as much as the first fine-tuning run.
Conclusion
Small language models are not a replacement for frontier LLMs. They are a better fit for a large share of enterprise work: bounded, high-volume, sensitive or latency-critical tasks. Frontier models remain the right tool for open-ended reasoning.
Use the four questions to decide per use case. Start from an open foundation model, fine-tune with efficient methods, and monitor for drift from day one. Then combine tiers in a hybrid architecture so each task gets the right model.
If you are weighing small language models against LLMs for a specific workload, contact ICANIO and our team will help you assess the options.
References
- Small language model (Wikipedia)
- Fine-tuning in deep learning (Wikipedia)
- Knowledge distillation (Wikipedia)
- LoRA: Low-Rank Adaptation of Large Language Models (arXiv)
- QLoRA: Efficient Finetuning of Quantized LLMs (arXiv)
- Hugging Face PEFT documentation
- Microsoft Phi models
- Google Gemma
Frequently asked questions
When should an enterprise choose small language models over an LLM?
Small language models are usually the better choice when the task is well-defined and bounded, the data is sensitive enough to require on-premises deployment, inference cost at high volume is a major concern, or latency requirements cannot be met by a cloud API round trip. If several of those conditions apply together, a fine-tuned small model is very likely the right fit.
How much can small language models reduce inference costs?
Savings depend on hardware utilization, model size and vendor pricing, so there is no single figure. Serving a 7 billion parameter open model on your own infrastructure is often an order of magnitude cheaper per token than calling a frontier API. The difference compounds at enterprise query volumes, so model your own traffic and current prices before committing.
Do small language models perform as well as LLMs on specific tasks?
For well-defined, domain-specific tasks, fine-tuned small language models can match or exceed frontier model performance, and the gap has narrowed considerably in recent years. Results still vary by task and data quality. The safest approach is to benchmark candidate models on a representative evaluation set built from your own production examples before choosing.
What does fine-tuning a small language model involve?
Fine-tuning usually starts from an open foundation model such as Phi-3, Gemma or Llama 3. Techniques like LoRA or QLoRA then adapt it using a curated dataset of domain examples. This needs far less compute and data than training from scratch. The most important investment is a clean, well-labeled dataset that reflects real production inputs.
Can small language models and LLMs work together in one system?
Yes. Hybrid architectures route high-volume, well-defined queries to fine-tuned small language models and escalate complex or ambiguous queries to frontier LLMs. A confidence-based router decides which tier handles each request. This pattern is increasingly common and often delivers better cost and performance than either model type alone.
Do small language models need ongoing maintenance?
Yes. Fine-tuned models can drift as products, rules and customer language change. They tend to fail confidently within their domain, which makes degradation harder to spot. Ongoing monitoring against an evaluation set, alert thresholds and scheduled retraining on fresh data keep small language models reliable over the long term.