Every team deploying artificial intelligence into enterprise workflows eventually asks the same question: how much should the AI do on its own? Human in the loop AI is the usual answer, but the debate around it tends to polarise. One side wants to automate everything the model can technically do. The other insists that a human must review every output before it takes effect.
Both positions miss the more precise human in the loop AI question. The real issue is not how capable the model is. It is this: if the model is wrong on a given decision, how serious is the consequence, and can the decision be reversed? Answering that clearly for each category of decision is the foundation of a workable human in the loop AI strategy and a durable agentic AI governance framework.
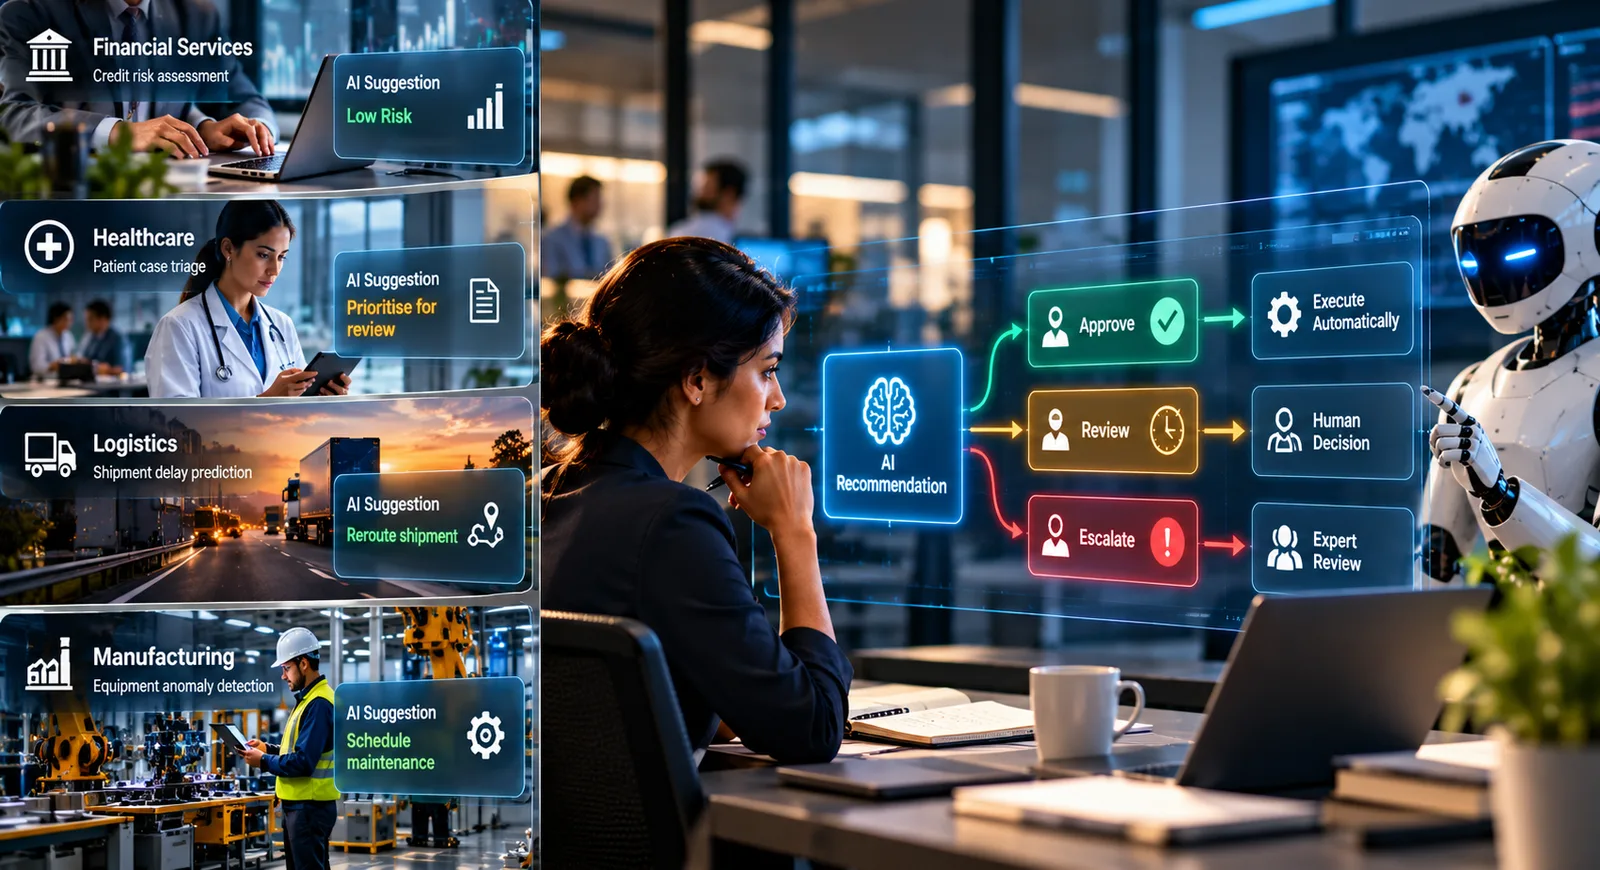
ICANIO's AgenticOps and Data and AI practices design human in the loop AI frameworks, AI decision making architectures, AI guardrails and oversight programs for enterprise teams. The patterns in this guide reflect what our team applies in production AI work across sectors such as financial services, healthcare, logistics and manufacturing.
Key Takeaways
- Human in the loop AI should be designed around consequence and reversibility, not model accuracy alone.
- AI decision making splits into decisions humans keep, decisions AI makes freely, and decisions AI makes within coded bounds.
- Agentic AI governance must define authority at the tool level, with audit trails and circuit breakers.
- AI guardrails turn policy into enforcement through schema checks, policy checks, rate limits and thresholds.
- An AI oversight framework mixes human-in-the-loop checkpoints with human-on-the-loop monitoring.
- Reversibility must exist before autonomy is granted, so mistakes stay cheap to undo.
Human in the Loop AI: The Question Teams Get Wrong
The human in the loop AI debate in most organisations starts from the wrong premise. Teams frame human in the loop AI around capability. Either the AI is accurate enough to be trusted, or it makes mistakes and humans must check everything. Both framings produce dysfunctional outcomes.
Full autonomy without appropriate oversight produces consequential errors with no recovery path. Full human review of every output produces a bottleneck with no real safety benefit. A person approving hundreds of AI-generated decisions per hour is not exercising judgment. That person is performing a ritual that looks like oversight without delivering it.
A well-designed human in the loop AI framework replaces the capability question with a consequence question. For each decision category, the team asks two things. How bad is the outcome if the AI is wrong? Can the decision be reversed once made? Those answers determine the right level of human involvement far more reliably than accuracy metrics.
A highly accurate model making irreversible decisions on regulated accounts still needs human oversight at the decision point. A less accurate model routing support tickets needs no human approval at all, because a mis-routed ticket is trivial to correct. Consequence-based decision mapping is the foundational human in the loop AI exercise. It produces a governance structure the business can defend and the operations team can actually run.
AI Decision Making: Four Categories That Set Oversight
A structured AI decision making framework divides the decisions an AI system touches into four groups. Each needs a different human in the loop AI design. Getting this right before building prevents the two most common agentic AI governance failures. The first is over-supervising low-stakes decisions until the AI adds no value. The second is under-supervising high-stakes decisions until an error causes a compliance incident.
| Category | Examples | Oversight model |
|---|---|---|
| 1. Humans decide | Credit approval, hiring, regulatory filings | Human-in-the-loop |
| 2. AI decides freely | Ticket routing, search ranking, drafts | Monitoring only |
| 3. AI decides within bounds | Refunds under a set limit | Coded limits, escalation |
| 4. Control architecture | Audit trails, circuit breakers, undo | Applies to all |
Category 1: Decisions that must remain with humans
These are irreversible decisions, contested decisions, and decisions where someone outside the system will ask who decided and expect a human name. Moving money between accounts, ending a customer relationship, approving credit, hiring and issuing a regulatory report all fit here. In these cases human in the loop AI applies fully: the AI decision making role is to support and inform, not to decide.
The reason is not that AI cannot produce a correct recommendation. It is that capability is not the same as permission. A decision that a regulator, auditor or customer will hold a human accountable for cannot be delegated to a model, whatever its accuracy. In regulated environments, our team documents this category explicitly in the agentic AI governance framework before go-live. Each decision type gets a named human owner and a documented escalation path.
Category 2: Decisions the AI makes without approval
These are high-volume, judgment-light decisions where mistakes are cheap and easy to fix. Ranking search results, routing requests, drafting a first version of a document, flagging items for review and categorising incoming data all belong here.
Applying human in the loop AI approval to these does not add safety. It adds latency and a bottleneck that defeats the purpose of the system. The right design is autonomous execution with monitoring, not autonomous execution without oversight. Outcomes are tracked, anomalies are detected and the system is adjusted when patterns emerge. No approval gate delays individual decisions.
Category 3: Decisions the AI makes within explicit bounds
This is where agentic AI governance precision matters most. "The AI can issue refunds up to a fixed amount without approval" is a boundary. "The AI can use good judgment on refunds" is a wish. It has no enforcement mechanism and no audit trail.
Bounded authority means the bounds live in the system, not in a policy document. The code enforces the limit. When a decision falls outside the bound, the system escalates rather than proceeding. This principle makes autonomous AI decision making trustworthy rather than merely fast.
Category 4: The control architecture around the rest
The fourth group is not a decision type. It is the AI oversight framework requirement that surrounds the first three. It includes:
- Bounded authority enforced in code.
- Reversibility designed in before autonomy is granted.
- Audit trails that record what the AI decided and why.
- Circuit breakers that halt autonomy when error rates cross a threshold.
- A cheap, documented escalation path for every decision type.
The order matters for any human in the loop AI programme. The undo capability, the circuit breaker and the audit trail must exist before autonomy is granted, not after the first incident forces a review.
Agentic AI Governance: Bounded Authority in Practice
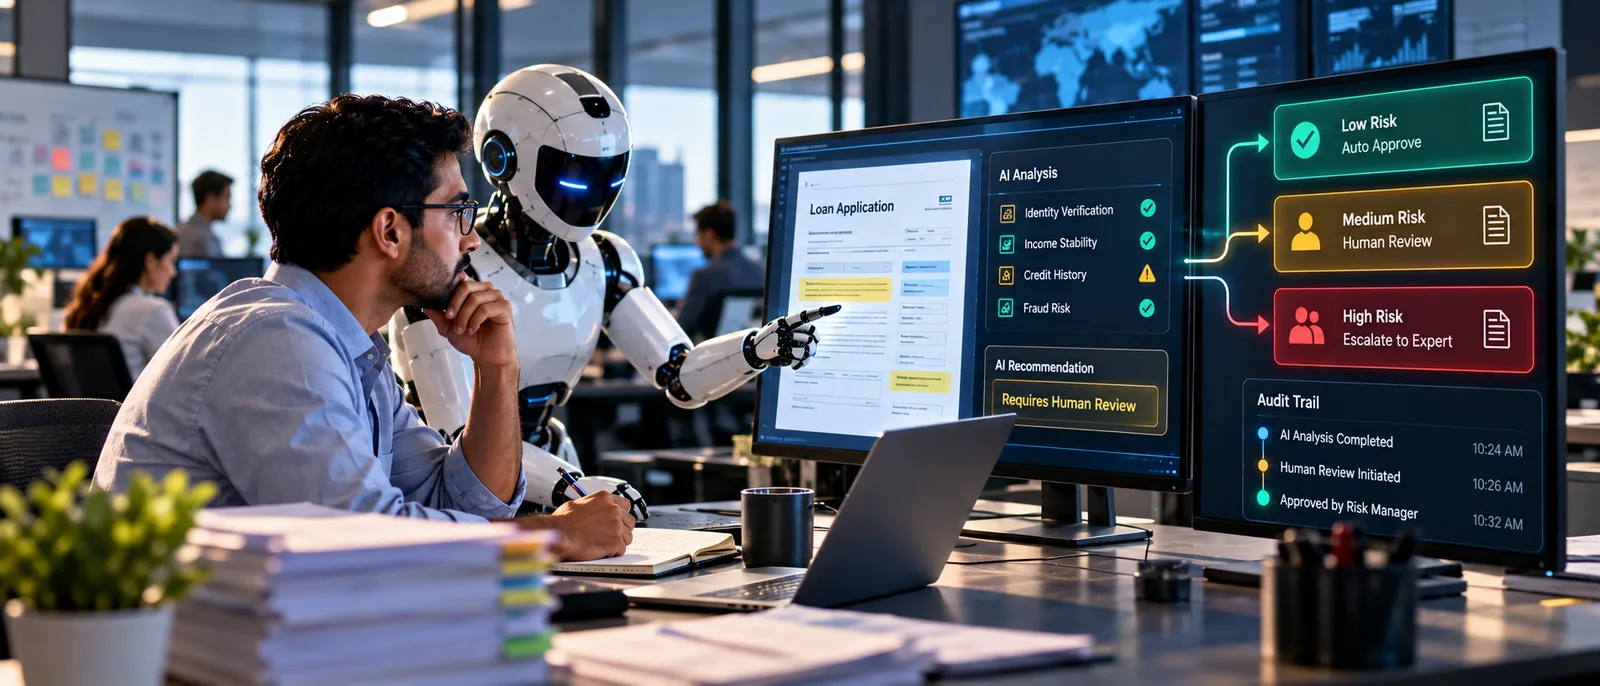
Agentic AI governance converts a human in the loop AI design into a system that can be operated, audited and trusted over time. Agentic systems plan multi-step actions, call several tools and adapt as they go. Poorly bounded governance therefore lets them drift outside their intended scope. Those drifts are hard to detect until an error has spread through several steps.
Effective agentic AI governance defines authority at the tool level, not just the system level. Without human in the loop AI boundaries, saying an agent may "manage customer communications" is not a policy.
A real policy specifies which channels the agent may use and what actions it may take in each. It sets the maximum value of any commitment, the conditions that force escalation and the audit format it must produce. That policy can be enforced, audited and amended. Our team treats tool-level authority documentation as a required deliverable before any agent reaches production. For deeper design patterns, see our guide to agentic AI architecture and multi-agent systems.
External frameworks point the same way. The NIST AI Risk Management Framework asks organisations to define roles, responsibilities and human oversight processes. In Europe, Article 14 of the EU AI Act sets human oversight requirements for high-risk AI systems. Neither prescribes a single human in the loop AI design, but both expect oversight to be deliberate and documented.
AI Guardrails: Turning Boundaries into Enforcement
AI guardrails translate agentic AI governance policies into technical enforcement. A policy that exists only in a document is not a guardrail. It is a statement of intent the system cannot enforce. Good AI guardrails embed authority boundaries in the system, so it cannot exceed them whatever the model recommends.
Several layers of AI guardrails are common in production agentic systems:
- Output schema validation blocks outputs outside the defined format or value range.
- Pre-execution policy checks confirm an action is within scope before it runs.
- Rate limiting caps actions per time window to what operators can monitor.
- Threshold enforcement escalates any decision that would exceed the authority bound.
- Circuit breakers halt autonomy when error, anomaly or escalation rates spike.
These layers should be non-bypassable parts of the architecture, not optional features someone can switch off when they cause friction. The OWASP Top 10 for Large Language Model Applications lists "excessive agency" as a key risk. Bounded tools and policy checks are exactly the controls that mitigate it.
AI Oversight Framework: Human-on-the-Loop vs Human-in-the-Loop
The difference between human-in-the-loop and human-on-the-loop is one of the most practical ideas in AI oversight framework design. Human-in-the-loop means a person approves individual actions before they take effect. Human-on-the-loop means a person supervises overall behaviour, watches for anomalies and intervenes when patterns look wrong, without approving each action.
For the categories above, the mapping is direct. Decisions that must stay with humans need human-in-the-loop oversight by definition. Decisions the AI makes within bounds need human-on-the-loop oversight. Someone monitors aggregate patterns, reviews the audit trail and watches circuit breaker thresholds, but does not approve each output.
Most production agentic systems need human-on-the-loop supervision for the bulk of autonomous work. They add human in the loop AI checkpoints only for decisions that cross an accountability, irreversibility or regulatory threshold. That blend keeps the system practical while preserving genuine accountability where it matters.
Applying human-in-the-loop supervision to every action is not a conservative position. It creates the illusion of oversight rather than its substance. When a human approves hundreds of decisions per hour, approvals become rubber stamps with accountability attached. That is worse than transparent autonomous operation with real monitoring. It concentrates blame on a person who never had a genuine chance to exercise judgment.
How to choose human in the loop AI or monitoring
- Ask whether the decision is reversible within minutes at low cost.
- Ask whether an external party will expect a named human to answer for it.
- Ask whether the volume makes individual review meaningful or merely symbolic.
- If the answers are yes, no and symbolic, use human-on-the-loop monitoring.
- If the decision is irreversible or externally accountable, keep a human in the loop.
Designing for Reversibility: The Undo Before the Autonomy
Reversibility makes agentic AI governance and human in the loop AI sustainable at scale. A system that can take irreversible actions without approval is a liability, whatever its accuracy. Even a very accurate system will make consequential errors when it runs at high enough volume. A system designed for reversibility recovers quickly. That reduces both the operational impact and the trust damage of each mistake.
Reversibility by design means every autonomous action either produces an easily reversible change or triggers an approval gate first.
Common patterns include database updates that can be rolled back and messages drafted but held until confirmed. Financial adjustments can sit in a pending state until cleared. These patterns allow broader autonomous AI decision making without the risk that irreversible actions carry. The cost of being wrong is then bounded by the cost of the undo, not by the full downstream impact of the error. Reversibility-first design lets the autonomy boundary be drawn more broadly than it otherwise could.
How to Roll Out Human in the Loop AI in Five Steps
Our team recommends a staged human in the loop AI rollout rather than a big-bang launch. Each stage widens autonomy only after the previous one has proven stable.
- Map decisions. List every decision the system will touch and score each for consequence and reversibility.
- Build controls first. Implement audit trails, undo paths and circuit breakers before enabling autonomy.
- Start in shadow mode. Let the AI recommend while humans decide, and compare outcomes.
- Grant bounded autonomy. Move low-risk categories to autonomous execution with monitoring.
- Review and adjust. Revisit bounds regularly using audit data and incident reviews.
This sequence fits naturally into existing DevOps and software development practice. Policy checks and guardrail tests can run in CI pipelines like any other test suite. Automation then keeps the controls consistent as the system evolves. If your organisation is also building a wider governance programme, our AI governance framework guide shows how human in the loop AI fits into enterprise policy.
Why Human in the Loop AI Matters After Launch
Human in the loop AI design is not finished at go-live. Models drift, business rules change and new tools get added to agents. Each change can move a decision from one category to another. A refund limit that was safe last quarter may be too generous after a pricing change.
Treat the human in the loop AI decision map as a living document. Review it whenever a model is retrained, a tool is added or a regulation changes. Monitor escalation rates too. A sudden rise often signals drift, while a sudden fall can mean a guardrail has been bypassed. Our article on AI project failure after launch explains the monitoring and ownership practices that keep these signals visible. You can also see how bounded agents work in practice in our agentic AI framework case study.
Conclusion
Human in the loop AI is not about distrust of machine learning. It is about matching oversight to consequence, and good human in the loop AI makes that match explicit. When teams classify decisions by severity and reversibility, the right design becomes clear: humans keep the decisions they must answer for, AI handles high-volume low-risk work, and everything in between runs inside coded bounds.
Strong agentic AI governance, non-bypassable AI guardrails and a practical AI oversight framework make that design real. Reversibility then keeps mistakes cheap. The result is an AI system that is both useful and defensible.
If you are designing an agentic system and want help mapping decisions, setting bounds or building guardrails, our team is happy to talk it through. Contact ICANIO to start the conversation.
References
- NIST AI Risk Management Framework
- OWASP Top 10 for Large Language Model Applications
- EU AI Act, Article 14: Human Oversight
- OECD AI Principles
Frequently asked questions
What is human in the loop AI?
Human in the loop AI is a design where human judgment is required at defined decision points before an AI output takes effect. It suits irreversible decisions, high-accountability decisions and cases where a regulator or stakeholder will hold a named person responsible. It differs from human-on-the-loop oversight, where people supervise overall system behaviour rather than approving each individual output.
How should AI decision making authority be structured?
AI decision making authority should follow consequence severity and reversibility rather than model accuracy. Irreversible or externally accountable decisions stay with humans. High-volume, low-consequence, easily reversible decisions run autonomously. Decisions in between run autonomously within explicit, code-enforced bounds, with escalation when a bound is exceeded. An AI oversight framework then monitors all categories continuously.
What is agentic AI governance?
Agentic AI governance is the set of policies, technical controls and monitoring that define what an AI agent may do. It enforces those permissions in code, records audit trails of agent actions and uses circuit breakers to return the system to human supervision when error or anomaly rates rise. Effective governance defines authority at the tool level, not just at the system level.
What are AI guardrails?
AI guardrails are the technical enforcement layers that keep an AI system within its authorised scope, whatever the model recommends. Typical layers include output schema validation, pre-execution policy checks, rate limiting, threshold enforcement and circuit breakers. Good guardrails are non-bypassable parts of the architecture rather than optional features that operators can disable when they create friction.
What is an AI oversight framework?
An AI oversight framework combines monitoring, audit requirements, escalation procedures and review cadences so an organisation can supervise AI behaviour in aggregate. A strong framework uses human-in-the-loop checkpoints for high-accountability decisions and human-on-the-loop monitoring for autonomous operations. It applies each model where it adds genuine oversight, rather than theatrical approval of every output.
Does human in the loop AI slow down operations?
It can, if applied to every decision. That is why consequence-based mapping matters. When human review is reserved for irreversible or accountable decisions, most work still runs autonomously at full speed. The goal is targeted human in the loop AI checkpoints, supported by monitoring, rather than blanket approval queues that create bottlenecks without improving safety.
How do you know when to widen AI autonomy?
Widen autonomy, and relax human in the loop AI checkpoints, only when evidence supports it. Useful signals include stable error rates in shadow mode, low and steady escalation rates, clean audit reviews and a tested undo path. Expand one decision category at a time, keep circuit breakers active and review the results before moving on. If the signals worsen, narrow the bounds again.