LLM evaluation before deployment is one of the most important quality controls in production AI engineering. It is also one of the most often skipped. The typical pattern is a manual spot-check. Someone runs a few prompts through the new model, the outputs look reasonable, and the model ships. That pattern breaks at scale. When a fine-tuned model trains on a new batch of data, its performance on held-out examples can degrade. Manual review often cannot see the drop. A model that scored well on the last run can score noticeably worse on the current one. Without an LLM evaluation gate, that degraded model goes live. It then produces incorrect outputs until someone connects the dots.
ICANIO builds automated model evaluation pipelines and LLM fine-tuning systems for enterprise clients. Our Data and AI and MLOps teams have applied this framework in regulated domains such as legal technology, healthcare and fintech document classification. This guide explains why LLM evaluation must be a hard gate. It shows how automated model evaluation works with the DeepEval framework. It also shows how to connect results to MLflow experiment tracking, so every training run leaves a documented, comparable record.
Key Takeaways
- Manual LLM evaluation fails at scale because it is slow, unrepeatable and biased toward hand-picked examples.
- A hard gate scores the full held-out validation set and promotes or holds each model version automatically.
- LLM-as-judge scoring with the DeepEval framework captures semantic correctness that exact-match metrics miss.
- MLflow experiment tracking turns every evaluation into a permanent, auditable record tied to a model version.
- Thresholds and evaluation cadence should be configured per tenant, based on the stakes of each use case.
Why Manual LLM Evaluation Before Deployment Fails
Manual LLM evaluation has three structural weaknesses. Each makes it unreliable as a quality gate.
Weakness 1: Scale
In a single-tenant setup with one model and one dataset, a reviewer can check a few dozen outputs and form a useful opinion. A multi-tenant LLM fine-tuning pipeline is different. Each client has its own fine-tuned model, trained on different data, on different schedules. Manual review quickly becomes the bottleneck. There is no realistic way to check every tenant before every deployment without review becoming the slowest step.
Weakness 2: Reproducibility
When a human approves a model, there is no structured record of what they checked. Nobody knows how many examples they reviewed or which criteria they applied. Six months later, the model starts producing odd outputs. It is then impossible to tell whether the issue existed at review time or emerged later. An LLM evaluation run tied to MLflow experiment tracking fixes this. It creates a permanent, queryable record of what was tested and what score was achieved, attached to a specific model version.
Weakness 3: Sampling Bias
A fine-tuned model can perform perfectly on the examples a reviewer happens to choose. Meanwhile it can regress badly on the overall data distribution. Manual review is biased toward memorable examples. A scoring function over the complete held-out validation set removes that bias. It surfaces regressions a manual check would miss.
The table below compares the two approaches.
| Factor | Manual spot-check | Automated LLM evaluation |
|---|---|---|
| Coverage | A few hand-picked prompts | Full validation set |
| Speed at scale | Slows with each tenant | Runs in parallel |
| Record | None or informal notes | Versioned MLflow run |
| Bias | Favours memorable cases | Whole distribution |
| Decision | Subjective | Threshold-based |
What a Hard LLM Evaluation Gate Looks Like
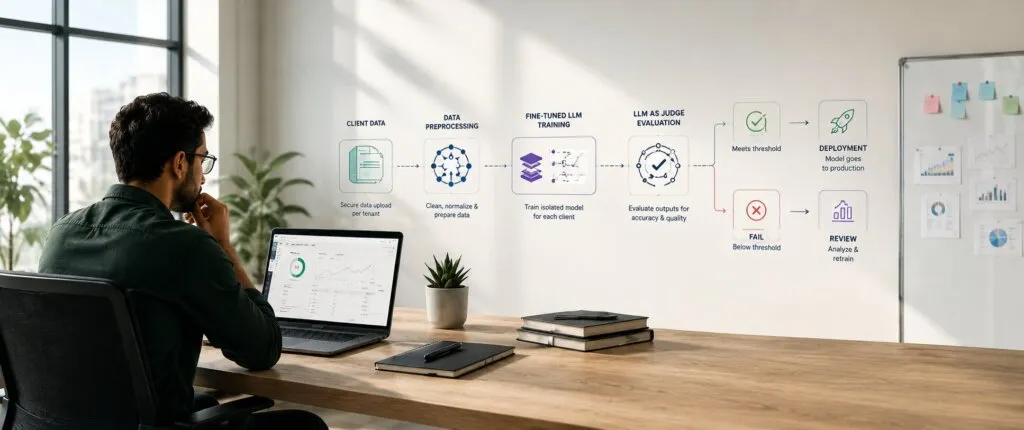
A hard LLM evaluation gate in an LLM fine-tuning pipeline follows a fixed sequence:
- A new model version is registered.
- The evaluation service runs the full held-out validation set through it.
- Every output is scored with a defined metric.
- Scores are aggregated into one accuracy figure.
- The model is promoted or held, based on a predefined threshold.
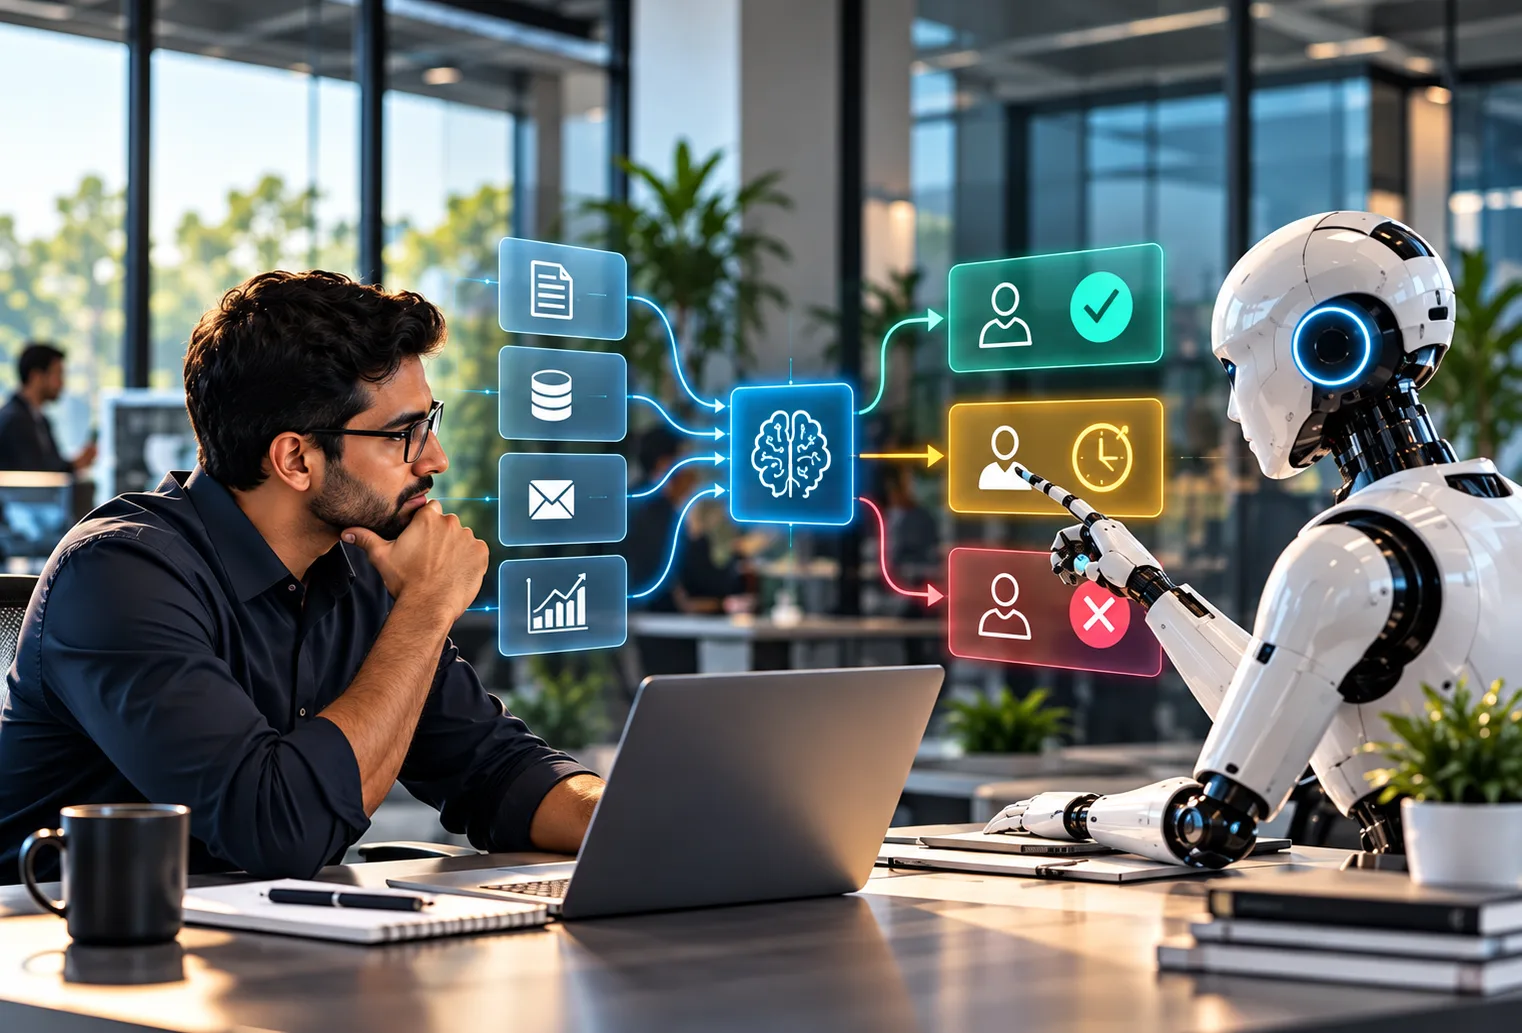
No human intervention is required for either outcome. The gate passes or holds the model and logs the result to MLflow experiment tracking either way. This produces three results at once: a deployed model that meets the bar, a held model that does not, and a permanent evaluation record for that version.
Why LLM-as-Judge Is the Right Scoring Approach
Traditional metrics such as exact match or F1 score work well when each input has one correct output. Generative tasks are different. Think of document classification with explanatory outputs. An answer can be semantically correct while phrased differently from the reference, and an exact-match scorer will penalise it.
The LLM-as-judge approach used in automated model evaluation solves this. A capable language model scores each prediction against the reference on correctness, relevance and faithfulness. The judge assesses semantic quality, which is what drives downstream task performance. Research such as Judging LLM-as-a-Judge examines both the strengths and the known biases of this method. Our team uses LLM-as-judge as the standard scoring method for generative tasks, with checks for judge bias.
How the DeepEval Framework Implements LLM Evaluation
The DeepEval framework provides a structured way to implement LLM evaluation with little boilerplate. It supports many metrics out of the box. One of them is GEval, which lets teams define custom correctness criteria in natural language. A judge model then scores predictions against those criteria. This makes the DeepEval framework well suited to domain tasks in legal, healthcare and fintech. In those fields, correctness is nuanced and hard to express as string matching.
Setting Up the Automated Model Evaluation Pipeline
The pipeline takes three inputs:
- The fine-tuned model to evaluate.
- The held-out validation set, formatted as test cases with input and expected output.
- The judge model that will score each prediction.
The judge should be a separate, more capable model than the one being evaluated. A model cannot reliably judge its own outputs. Using the same model as subject and judge produces optimistic scores. For each test case, the DeepEval framework runs the input through the fine-tuned model. It passes the prediction and expected output to the judge and receives a score between 0 and 1.
Scores are then aggregated across the full validation set. The result is an overall accuracy figure for the whole data distribution, not a selected sample.
Connecting DeepEval to MLflow Experiment Tracking
Automated model evaluation results only become a useful gate when tied to a specific model version. This is where MLflow experiment tracking becomes essential. Every LLM evaluation opens a matching MLflow run linked to the training run. The mapping is simple:
- DeepEval scores are logged as metrics.
- The promotion decision is logged as a tag.
- The validation set is logged as an artifact.
- The threshold and judge model are logged as parameters.
For any model version in the registry, a team can retrieve the exact score, validation set and threshold applied. Nobody has to rely on documentation or memory. This matters for organisations whose AI audits require evidence of quality review before deployment. ICANIO integrates this tracking as a standard part of the enterprise AI pipelines we build.
LLM Fine-Tuning Pipeline: Threshold Configuration
The accuracy threshold that decides promotion should be configurable per tenant, not hardcoded globally. Organisations tolerate classification errors differently. A legal team processing high-stakes contracts may need a much higher bar than a content tagging pipeline. Making the threshold a per-tenant parameter keeps the gate flexible. It serves many clients, on different training schedules, without architectural changes to the LLM fine-tuning pipeline.
Document each threshold alongside its rationale. When the gate holds a model, both the engineering team and the client should understand why that threshold applies. We recommend agreeing threshold values as part of the service design specification. They should then be logged to MLflow with the rest of the evaluation configuration.
Review thresholds periodically as each use case matures. A conservative early threshold may rise once the model proves stable. A use case that expands into higher-stakes document types may need a stricter bar. The evaluation architecture should make these changes easy, without redeploying the evaluation service.
The LLM Evaluation Record as a Trust Asset
Beyond gating releases, a well-structured LLM evaluation process builds a documented history of model quality. Suppose a client asks why accuracy changed between last month and this month. The answer should come straight from the MLflow history. It shows which dataset version was used and what the score was. It also shows whether new training data introduced a distribution shift on previously stable document types.
When an auditor asks for evidence that models are reviewed before deployment, the answer is the run history. It is a timestamped, reproducible record for every model version. Scores, validation artifacts, promotion decisions and training lineage sit in one place. This trust layer helps make artificial intelligence deployable in regulated environments. Frameworks such as the NIST AI Risk Management Framework expect exactly this kind of measurable, documented testing.
5 LLM Evaluation Mistakes to Avoid
Several recurring mistakes undermine automated model evaluation programs. They appear across teams at different maturity levels, and each produces a predictable failure.
- Evaluating on the training set. Scores look optimistic and do not reflect real performance. Reserve a separate validation split before training begins.
- Using the fine-tuned model as its own judge. Self-assessment inflates scores. Use a separate, stronger judge model.
- Setting one global threshold. A single bar ignores the different stakes of each tenant. Configure thresholds per use case.
- Not logging results. If an LLM evaluation is not stored in MLflow, it never happened as far as an audit is concerned. Every run must leave an artifact.
- Treating a pass as permanent. Quality can degrade as production data drifts. Evaluation should run on a schedule, not only at first release.
These mistakes are easy to make under delivery pressure. Our team recommends turning each one into an automated check in the pipeline. That way, the guardrail does not depend on anyone remembering it.
LLM Evaluation Cadence and Distribution Shift Monitoring
LLM evaluation is not a one-time event at first release. As production data evolves, inputs can diverge from the data the model was trained and validated on. This is known as concept drift. It can degrade accuracy on document types or phrasing that were rare in the original training data. Scheduled LLM evaluation with validation sets refreshed from current production data catches this drift early.
Scheduled Evaluation
For each client in a multi-tenant LLM fine-tuning pipeline, the evaluation cadence should be part of the service specification. High-stakes clients in legal or healthcare may warrant weekly runs against a rotating validation sample. Lower-stakes content classification may need only monthly runs. The key point is that cadence is a deliberate choice, not a default omission. ICANIO makes cadence a configurable parameter per tenant. Clients can adjust frequency as their data volume changes, without architectural changes.
Event-Triggered Evaluation
Event-triggered evaluation is a second mechanism worth adding in mature pipelines. When production monitoring detects a significant change in input distribution, an automated trigger starts an LLM evaluation cycle. It uses a fresh validation sample drawn from recent production data. This gives faster feedback than a fixed schedule. It also avoids the compute cost of continuous evaluation for stable use cases.
| Trigger | When it runs | Best for |
|---|---|---|
| New model version | Every training run | All tenants |
| Schedule | Weekly or monthly | Stable use cases |
| Drift alert | On distribution change | High-stakes tenants |
| Threshold change | After config update | Audited workflows |
Combining these triggers covers both time-based quality drift and sudden data shifts.
How LLM Evaluation Fits Into MLOps and DevOps
An LLM evaluation gate works best as one stage in a wider delivery pipeline. In DevOps terms, it is a quality gate similar to unit and integration tests. The difference is that it tests a machine learning artifact rather than application code. Automation is what makes it reliable. The gate should run on every candidate model, without manual triggers.
Good data engineering underpins all of this. Validation sets must be versioned, representative and free of training leakage. Our team treats the validation dataset as a first-class asset, with its own owner and change history. For a deeper look at the training side, read our article on the multi-tenant LLM fine-tuning pipeline. The related multi-tenant LLM fine-tuning case study shows a six-stage pipeline in practice. If you are still choosing an approach, our guide to RAG vs fine-tuning can help.
Security also deserves a place in the gate. The OWASP Top 10 for LLM Applications lists risks such as prompt injection and sensitive data disclosure. Adding targeted test cases for these risks makes the gate cover safety as well as accuracy.
Conclusion
LLM evaluation before deployment should be a hard, automated gate, not a manual spot-check. Scoring the full validation set with an LLM-as-judge, through the DeepEval framework, removes bias and scales across tenants. Logging every run to MLflow experiment tracking creates the audit trail regulated teams need.
Per-tenant thresholds, deliberate cadence and drift-triggered runs keep the gate useful long after first release. Together, these practices turn LLM evaluation into a trust asset for clients and auditors. ICANIO's Data and AI services and DevOps and cloud engineering services help teams build these pipelines.
If you want help designing an evaluation gate for your models, contact ICANIO to speak with our MLOps engineers.
References
- DeepEval: Getting started
- DeepEval: G-Eval metric
- MLflow Tracking documentation
- Judging LLM-as-a-Judge with MT-Bench and Chatbot Arena (arXiv)
- NIST AI Risk Management Framework
- OWASP Top 10 for LLM Applications
- Concept drift (Wikipedia)
- F-score (Wikipedia)
Frequently Asked Questions
What is automated model evaluation for LLM fine-tuning?
Automated model evaluation runs a held-out validation set through a newly trained model and scores every output with a defined metric. It then promotes or holds the model based on whether the aggregate score clears a predefined threshold. In an LLM fine-tuning pipeline, this LLM evaluation step replaces manual spot-checking as the quality gate before any model version reaches production.
Why use the DeepEval framework specifically?
The DeepEval framework provides a structured LLM-as-judge implementation with configurable metrics, including GEval for custom correctness criteria. It works well with MLflow experiment tracking. It supports domain tasks in legal, healthcare and fintech, where exact-match scoring misses outputs that are semantically correct but phrased differently from the reference answer.
How does MLflow experiment tracking support LLM evaluation?
MLflow provides a permanent, queryable record of every LLM evaluation run, attached to the model version that was evaluated. It stores DeepEval scores as metrics, the promotion decision as a tag and the validation set as an artifact. Any model version can then be reconstructed and audited without relying on documentation or anyone's memory.
What threshold should be used for the evaluation gate?
Set thresholds per tenant, based on the operational stakes of each use case, and document the rationale. Legal and healthcare use cases usually need higher thresholds than content tagging. Agree the threshold as part of the service design specification and log it to the tracking system. Review it as the use case matures or expands.
How often should LLM evaluation run after deployment?
Run it on every new model version, and also on a schedule that matches the stakes. High-stakes tenants may need weekly runs, while stable, low-risk use cases may need monthly runs. Add event-triggered runs when monitoring detects a shift in input data, so drift is caught quickly without paying for continuous evaluation.
Can a model act as its own judge in LLM evaluation?
It should not. A model judging its own outputs tends to produce optimistic scores that do not reflect real performance. Use a separate, more capable judge model, and log which judge was used for each run. Our team also recommends periodic human review of a small sample of judge decisions to check for judge bias.