Most enterprise AI programs do not die in a dramatic failure. They die quietly, a few months after a successful pilot. The model that impressed everyone in a demo never quite reaches the systems people actually use. AI project failure, in practice, usually looks less like a broken algorithm and more like a program that ran out of momentum before production. The same mistakes keep repeating, even as tooling improves.
ICANIO's AI/ML Center of Excellence works with enterprises to close the gap between a working prototype and a system that survives production data, real users, and regulatory scrutiny. The patterns below are the ones that show up most often. The fixes are less about better models and more about better engineering discipline.
Key Takeaways
- AI project failure usually starts with data quality and infrastructure gaps, not with model accuracy.
- The move from pilot to production is a separate phase with its own budget, testing and monitoring.
- Every production model needs one named owner and a documented escalation path.
- Machine learning engineering and change management skills are as important as data science.
- Simple, enforced AI governance catches drift and bad decisions before they become incidents.
What Is AI Project Failure, Really?
It helps to define the term before diagnosing it. An AI project failure is any initiative that does not deliver lasting business value from a model. Sometimes the model never ships. Sometimes it ships and nobody uses it. Sometimes it is used for a while and then quietly degrades until people stop trusting it.
All three forms of AI project failure share a root cause. The organization treated the model as the product, when the real product is a system: data pipelines, integration, monitoring, ownership and the people who work with the outputs. When any part of that system is missing, the whole program is exposed.
This framing changes where you look for the source of AI project failure. Teams that blame the algorithm often hit the same wall again.
Six Common Causes of AI Project Failure at a Glance
The table below summarises the six causes covered in this guide and the first fix our team recommends for each.
| Cause | Typical symptom | First fix |
|---|---|---|
| Poor data quality | Demo works, live data breaks it | Data audit before modelling |
| Pilot treated as finish line | Stalls after sign-off | Budget a production phase |
| No model owner | Bad outputs go unreported | Name one accountable owner |
| Skills gap | Nobody can operate the model | Add ML engineers early |
| Weak vendor choice | Lock-in, integration friction | Paid PoC on real data |
| Paper governance | Drift goes unnoticed | Monitor and set triggers |
Each cause is explained in detail below, with practical steps to reduce the risk of AI project failure in your own programme.
The Data Problem Nobody Wants to Own
Ask about any AI project failure and the honest answer, more often than not, starts with the data. A model trained on a clean, curated dataset can look excellent in a proof of concept. Then it falls apart once it meets the real thing. Customer records are split across three systems. Sensor data has gaps no one flagged. Labels mean something different to every team that touched them. None of this shows up until the model runs on live traffic instead of a hand-picked sample.
The deeper issue is that no one owned data quality as a deliverable in its own right. It is a less exciting phase than building the model. But skipping it is one of the most reliable routes to AI project failure once the system leaves the lab. Enterprises that treat a data audit as a prerequisite, not a formality, tend to catch these problems while they are still cheap to fix.
Infrastructure built for a different workload
Infrastructure follows a similar pattern. Many IT environments were built for transactional workloads, not for model training and inference at scale. Teams that discover this only after a pilot succeeds end up rebuilding the foundation mid-project. That rebuild is a costly, avoidable form of AI project failure.
A simple data readiness checklist
A basic inventory catches most of the problems that later get blamed on the model. Our team recommends answering these questions before any modelling starts:
- Where does each data source live, and who owns it?
- How often does each source change, and is that change logged?
- Are labels defined the same way by every team that uses them?
- What share of records are incomplete, duplicated or out of date?
- Can the production environment deliver this data at the speed the model needs?
The general discipline of data quality covers accuracy, completeness, consistency and timeliness. Each of those dimensions maps directly to a way a model can fail in production. Strong data engineering is the cheapest insurance against AI project failure.
Why Pilots Rarely Survive the Trip to Production
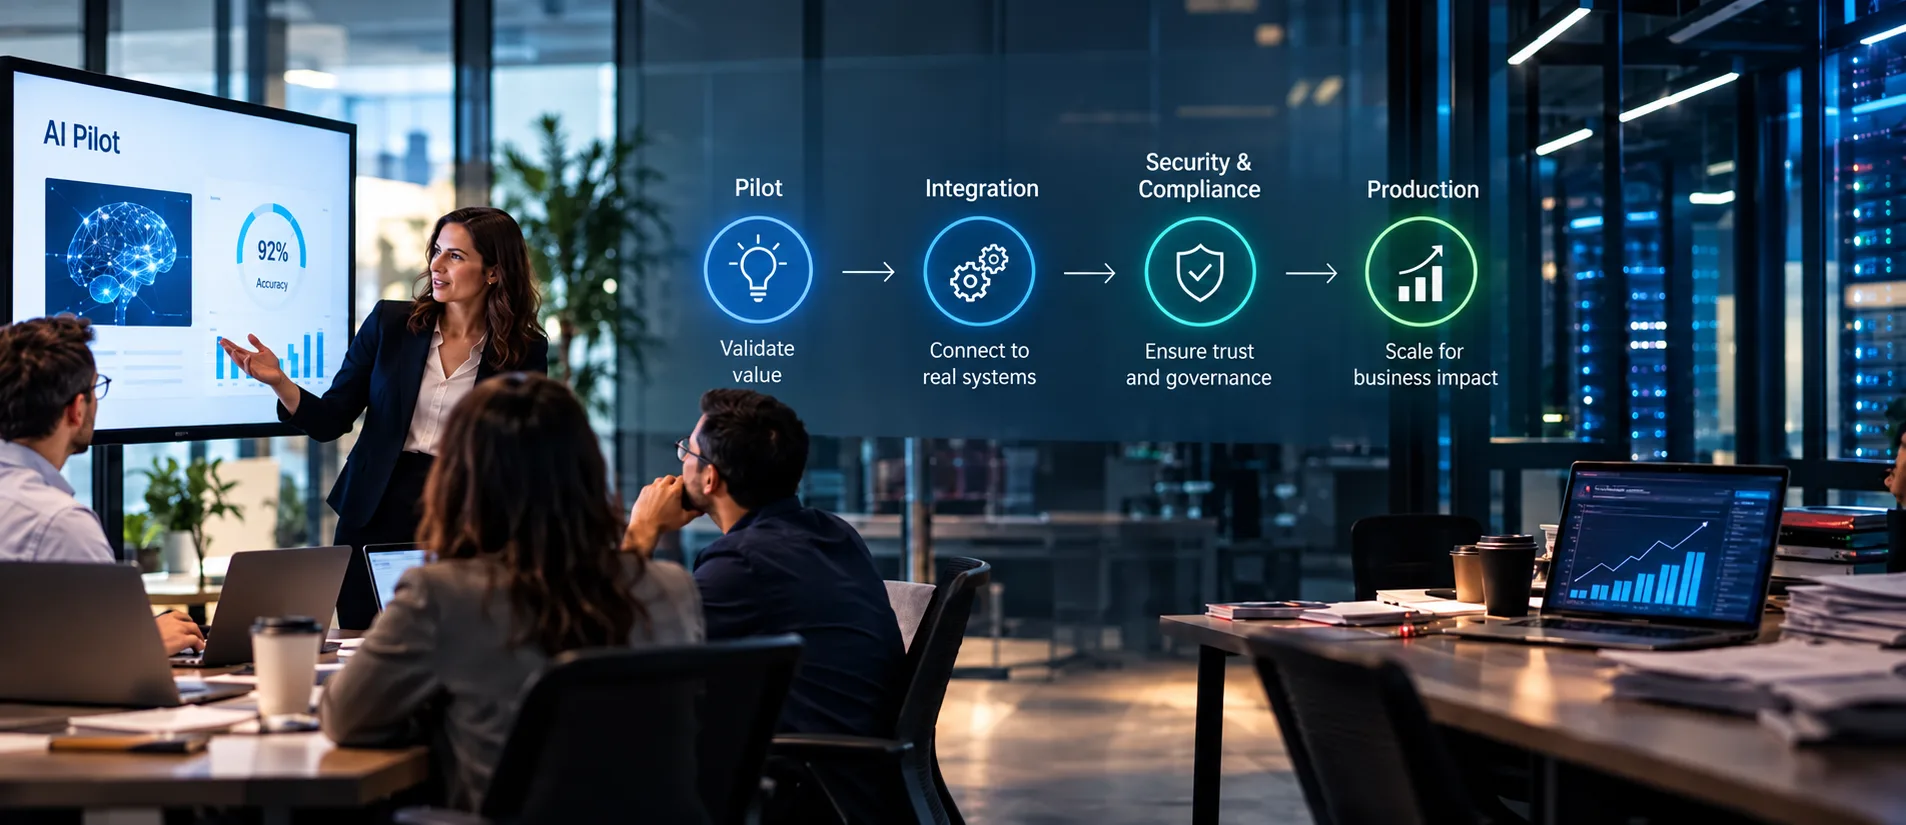
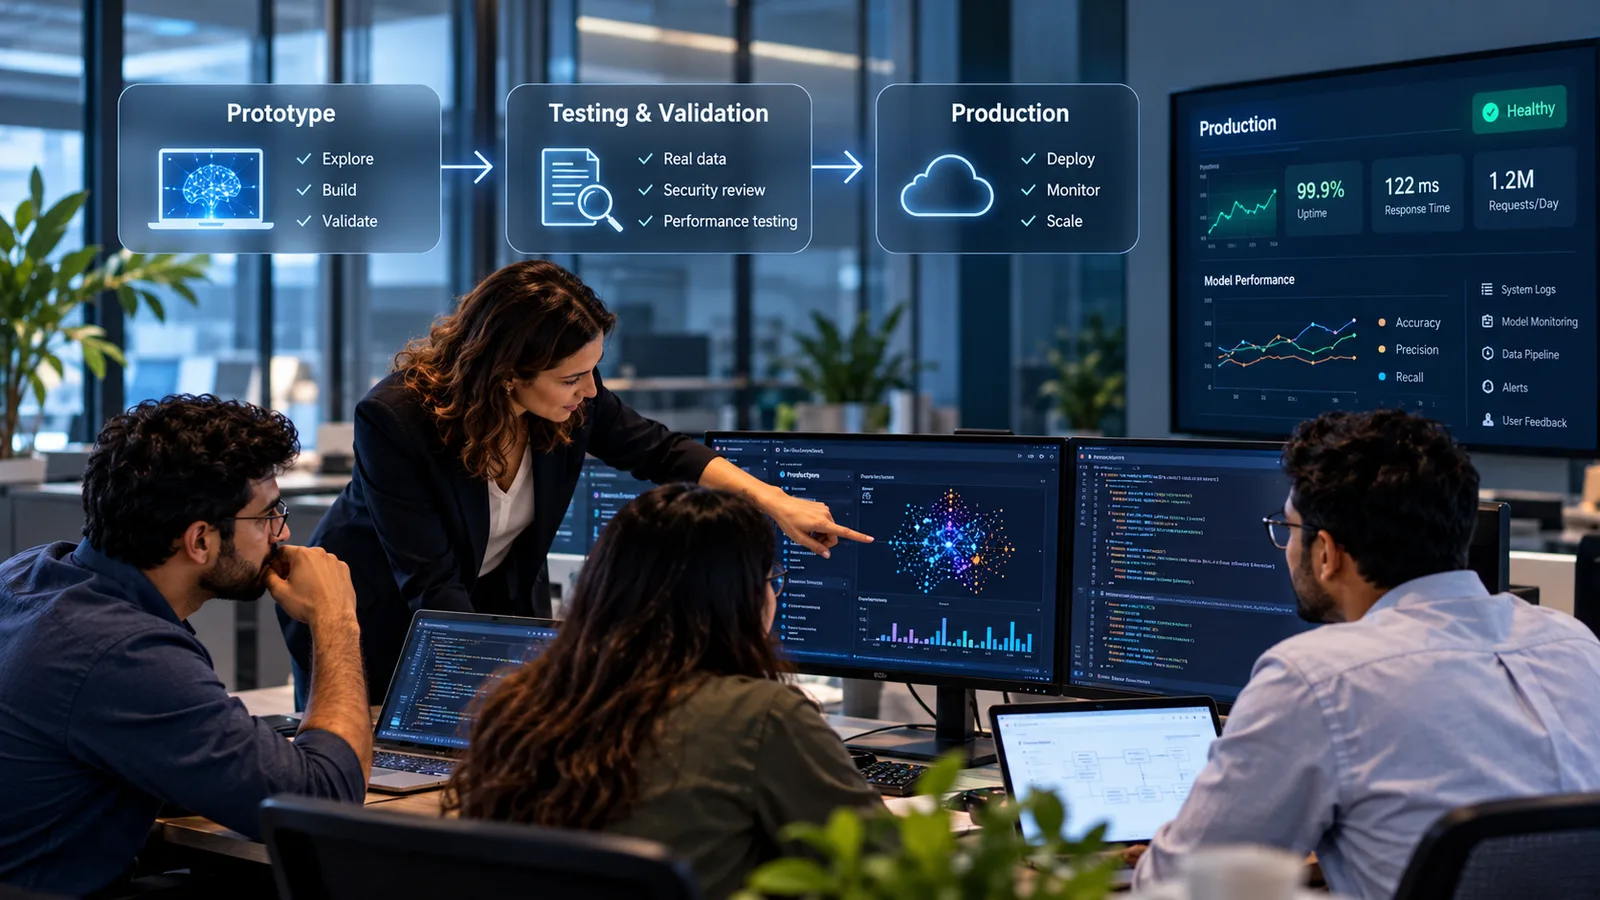
A large share of machine learning pilots never make it past the pilot stage. The reason is rarely the model's accuracy. Moving from pilot to production asks for things a pilot was never built to handle. These include integration with existing systems, a security review, and monitoring that can tell you when the model starts drifting. They also include a plan for what happens if the model gets something wrong in front of a customer.
Enterprises that treat the pilot as a finish line, rather than the first phase of a longer build, are the most likely to suffer AI project failure. A pilot-stage model often has to be rebuilt as a production service, with proper testing and observability included from the start. Budgeting for that second phase up front, rather than treating it as scope creep, is often the difference between a model that ships and one that sits in a repository.
MLOps as the bridge
The practice of MLOps exists to close exactly this gap. It applies DevOps ideas, such as automation, versioning and continuous delivery, to machine learning systems. Google's guide to MLOps continuous delivery and automation pipelines describes maturity levels that move from manual, notebook-driven work to fully automated training and deployment. Most stalled pilots sit at the manual level.
Regulated sectors face a wider gap
The pilot to production gap tends to be widest in regulated sectors. There, a production system has to satisfy audit and compliance requirements a pilot never faced. Enterprises that build this expectation into the plan from day one spend far less time rebuilding what already looked finished.
Be honest about timelines too: a six-week pilot does not imply a six-week production build. For a deeper walkthrough, see our guide on scaling AI from PoC to production.
Nobody Owns the Model, So Nobody Catches the Problem
Ask a room full of stakeholders who is accountable when a production model makes a bad call. You will often get silence. That silence is where AI project failure takes root. Without a named owner, there is no clear process for reviewing an unexpected output, escalating it, or deciding whether the model needs retraining. The ambiguity gets more expensive the longer a system runs unsupervised.
Ownership gaps make AI project failure especially costly in regulated environments. Financial services and manufacturing firms face real scrutiny over automated decisions. A governance policy that only exists on paper does not hold up under that scrutiny. The fix is not complicated:
- Name one accountable owner per production model.
- Document an escalation path for unexpected outputs.
- Check regularly whether training data still reflects the population the model serves.
- Keep an audit trail that links each decision to its data and logic.
Business owner versus technical owner
Enterprises that get this wrong tend to share a specific pattern. The business owner of the model and its technical owner were never the same person. Neither felt responsible once the system reached a customer. Naming a single accountable owner before launch, not after the first incident, is the clearest way to prevent this kind of AI project failure.
A simple audit trail helps too. If a model's decision can be traced back to the data and logic that produced it, disputes get resolved in minutes. Without it, they become weeks-long investigations that erode confidence in the whole program.
The Skills Gap That Never Makes It Into the Budget
A surprising number of implementation problems have nothing to do with the model. They have everything to do with who is around to keep it running. Data science teams are built to develop models. The machine learning engineering and platform operations skills needed to deploy and monitor those models are a separate discipline. Many organizations only discover the gap after the model is live and something breaks with no one on call who understands it.
Pairing every data science hire with a machine learning engineer from the outset addresses much of this before it surfaces. It is worth saying plainly: a technically excellent model that no one on the operations side understands is still a liability. Left untended, it becomes an AI project failure regardless of its test scores.
Change management is half the job
Change management is the other half of the skills problem. A model that changes how people work needs training. It needs honest communication about what it does and does not decide. It also needs a way for employees to flag outputs that look wrong.
Skip change management, and AI project failure follows even when the model performs well. The people who were supposed to use it never trusted it. Our article on enterprise AI transformation and upskilling covers how to plan for this early.
Choosing a Vendor Without Getting Burned
In vendor-driven AI project failure, the story often starts with a demo. A polished sales demo is not evidence that a platform will work on your data. It is evidence that it works on the vendor's data. Enterprises that skip a proof of concept against their own production-representative data tend to discover the gap after signing a long-term contract. By then, integration friction and format lock-in are already expensive to unwind.
Most vendor-related AI project failure is not about accuracy. It is about flexibility. Organizations increasingly favour platforms that avoid locking data into a proprietary format. That includes low-code and no-code tooling that can adapt as requirements change. Rigid products that need a full rebuild the moment the business shifts direction are a common contributor to AI project failure.
How to run a fair vendor test
The cheapest way to test a vendor is to insist on a short, paid proof of concept against real data before committing to a multi-year contract. Vendors confident in their product rarely object. The ones that do are telling you something worth hearing. Our team suggests scoring each vendor on data portability, integration effort, monitoring support and exit cost, not just on accuracy.
Governance That People Actually Follow
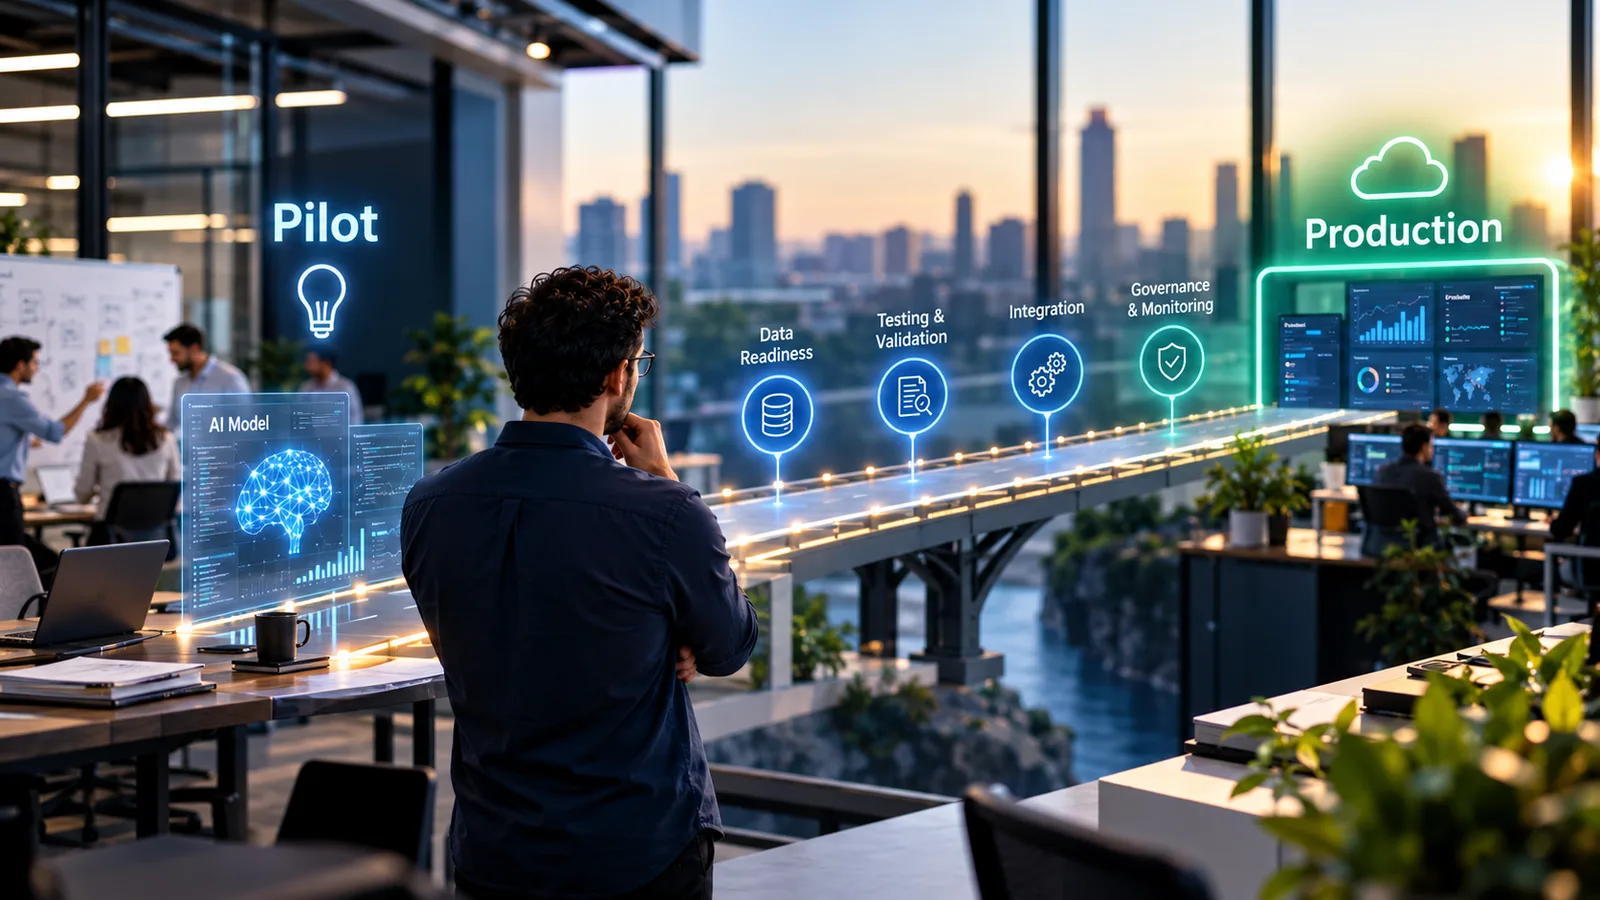
A governance framework is only useful if people follow it. That means it needs to be simple enough to survive a busy team. The essentials of AI governance are narrow:
- Someone approves a model before it reaches production.
- Someone monitors how it performs over time.
- There is a clear trigger for retraining or pulling it back.
More enterprises are formalising AI governance now, partly because regulators are starting to expect it. The NIST AI Risk Management Framework is a useful, freely available reference. It organises AI risk work into four functions: govern, map, measure and manage.
Start small and expand
Most enterprises that get this right start with one high-risk model. They prove the process works, then expand it. That incremental approach lets AI governance mature alongside the AI program itself. The alternative is bolting it on after an AI project failure has already damaged trust.
A structure built this way also catches early warning signs of AI project failure. These include model drift, rising override rates and unexplained decisions. Catching them early means fixing them before they turn into a visible incident. Our AI governance framework guide goes further on policies and roles.
How to Prevent AI Project Failure: A Practical Roadmap
Here is a sequence our team recommends for new initiatives, drawn from the patterns above:
- Define the business outcome. Write down the decision the model will support and how success will be measured.
- Audit the data. Inventory sources, owners, quality and refresh rates before any modelling.
- Plan the production phase. Budget integration, security review and monitoring from day one.
- Name the owner. Assign one accountable person and a documented escalation path.
- Staff for operations. Pair data scientists with ML engineers and plan change management.
- Test vendors on real data. Run a short, paid proof of concept before signing.
- Govern lightly but consistently. Approval, monitoring and retraining triggers for every model.
Skipping even one step reopens a path to AI project failure.
Why the roadmap works
Each step removes one of the six causes of AI project failure described earlier. Together they turn an experiment into a managed system. The AWS Machine Learning Lens of the Well-Architected Framework offers a similar lifecycle view, covering problem framing, data processing, model development, deployment and monitoring.
Warning Signs Your Project Is Heading Toward Failure
Early warning signs of AI project failure include:
- Nobody can say who owns the model in production.
- The pilot dataset was hand-picked and never refreshed.
- There is no budget line for integration or monitoring.
- Users work around the model instead of with it.
- Override rates rise and nobody investigates why.
If two or more of these apply, pause and fix the foundation before adding features. A short delay now is far cheaper than a full AI project failure later.
Conclusion
AI project failure is rarely a mystery. It follows a small number of predictable patterns: weak data quality, pilots treated as finish lines, missing ownership, skills gaps, rushed vendor choices and governance that exists only on paper. Each pattern has a practical fix, and none of those fixes depends on a better algorithm.
The organizations that succeed treat AI as an engineering system rather than a science experiment. They plan the pilot to production phase early, staff for operations, invest in change management and keep governance simple enough to follow. Our data and artificial intelligence services are built around that approach, and our post on AI project failure after launch covers what happens once a model is live.
If you want to avoid AI project failure in your next initiative, or rescue a current one, our team is happy to talk it through. Contact ICANIO to start the conversation.
References
- NIST AI Risk Management Framework
- MLOps: continuous delivery and automation pipelines in machine learning (Google Cloud)
- Machine Learning Lens, AWS Well-Architected Framework
- MLOps (Wikipedia)
- Data quality (Wikipedia)
Frequently asked questions
What is the most common cause of AI project failure?
Data quality and infrastructure gaps top the list. Models that perform well on curated data often struggle once connected to messy, real production data. Investing in data architecture and a proper data audit before model development tends to produce a much smoother path to production later on, and it is far cheaper than rebuilding a model after launch.
Why do so many AI pilots never reach production?
Pilots are usually built to prove technical feasibility, not to handle integration, security review, or ongoing monitoring. The gap between a notebook and a live system is easy to underestimate. It is one of the clearest reasons a pilot that looked entirely successful never ships. Budgeting a separate production phase from the start closes most of that gap.
How long does moving from pilot to production usually take?
It varies by industry and regulatory context. Enterprises should expect a distinct phase for integration, security review and monitoring setup rather than a quick handoff. Rushing this stage is a common cause of a rocky rollout. A phased approach with clear checkpoints, and honest timelines agreed before the project starts, tends to reduce the risk considerably.
What should a basic AI governance process include?
At minimum, clear ownership for model approval, ongoing performance monitoring, and a defined trigger for retraining or rollback. Data lineage documentation matters too, since it lets a team trace which data shaped a disputed decision. Frameworks such as the NIST AI Risk Management Framework provide a free, structured starting point for building these processes.
Do smaller initiatives face the same risk of AI project failure?
Yes. Data quality, governance and change management problems do not scale down with the size of the initiative. A small pilot without monitoring or a clear escalation path is just as exposed as a large, multi-region rollout. The fixes are simply lighter: one owner, one checklist and one monitoring dashboard can be enough to start.
How can a team recover from AI project failure?
Start by checking the foundations rather than the model. Confirm who owns it, whether the data still reflects reality, and whether monitoring and integration were ever properly built. Fix those gaps first. Many stalled projects recover once the surrounding system is in place, without any change to the underlying model or algorithm.