AI project failure is rarely dramatic. Systems do not crash on launch day with visible error messages. They degrade quietly. Dashboards stay green. Confidence scores remain high. Usage metrics look acceptable.
Underneath the surface, though, the model is drifting away from the data it was trained on. Prediction accuracy erodes. The gap between what the system outputs and what the business needs keeps widening. By the time the operations team acknowledges the AI project failure, credibility is already damaged. Recovery then costs far more than preventive maintenance would have. Understanding why AI project failure happens after launch is the first step toward building systems that deliver durable value rather than short-lived demonstrations.
ICANIO's Data and AI practice designs post-deployment AI governance frameworks, MLOps monitoring programs and model drift detection for enterprise teams. The failure patterns, monitoring approaches and governance practices in this guide reflect what our team sees in production machine learning programs across different industries.
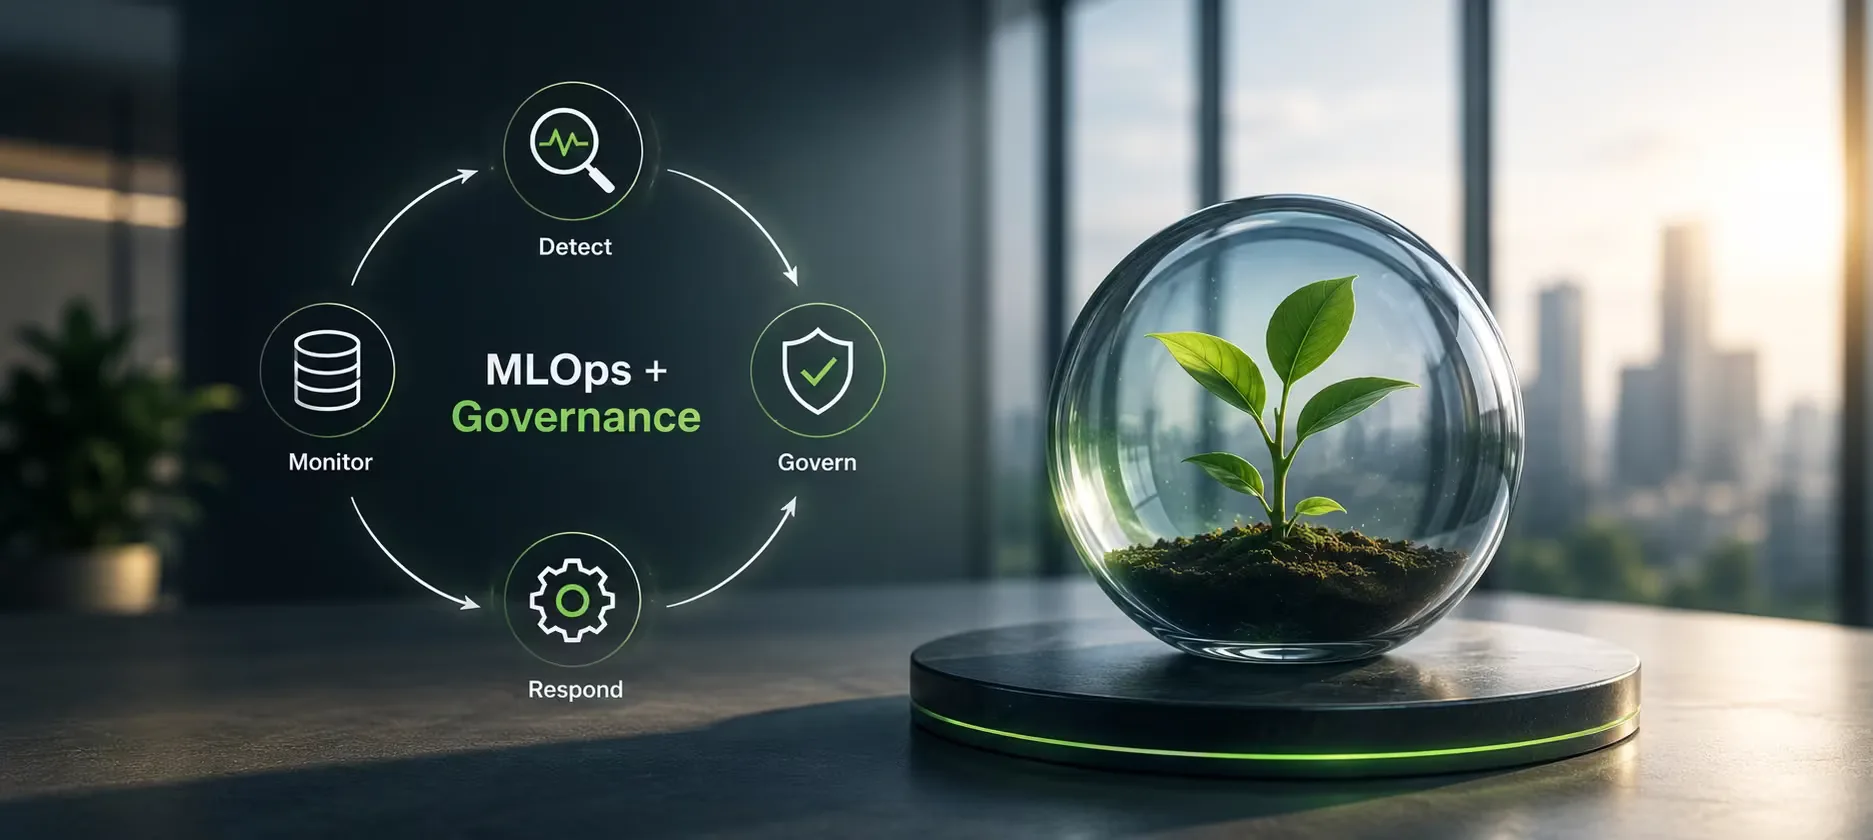
Key Takeaways
- Most AI project failure is a slow decay after launch, not a visible crash on day one.
- AI model drift is a certainty in changing environments, so detection and retraining must be designed in from the start.
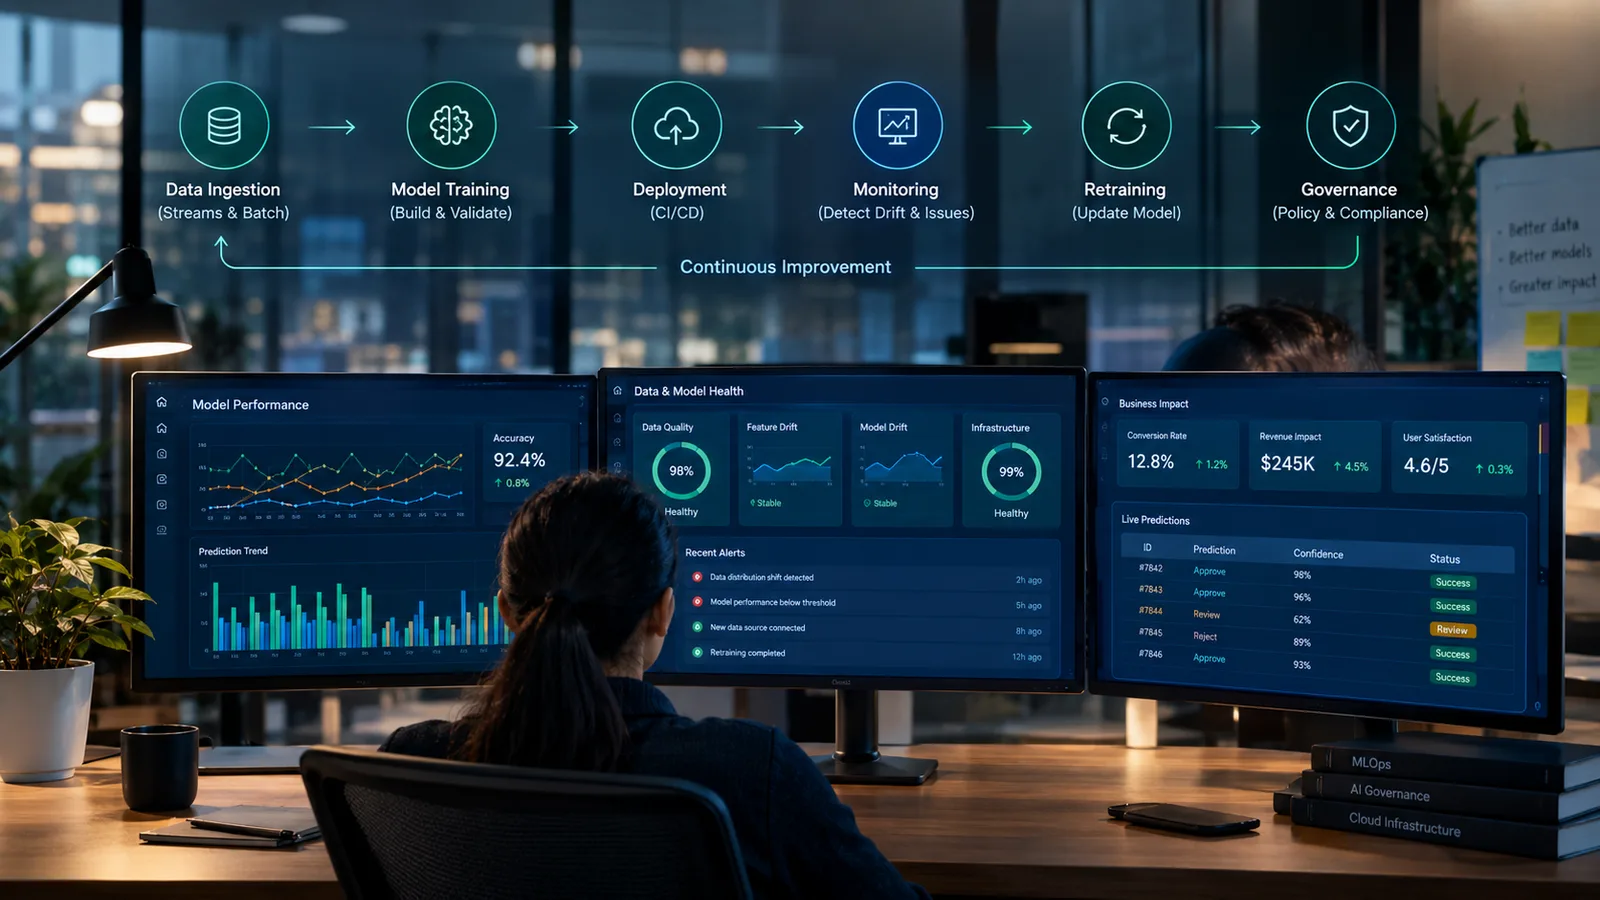
- MLOps monitoring should cover data quality, model performance, feature distributions, business KPIs and infrastructure.
- A single named owner for each post-deployment AI system closes the ownership vacuum behind many failures.
- AI governance (retraining policies, thresholds, explainability and bias checks) keeps a model trustworthy for its whole lifetime.
- Six recurring failure modes, from training-serving skew to missing fallbacks, can each be prevented at design time.
AI Project Failure: Why It Happens After Launch
The most common form of AI project failure is not a spectacular breakdown. It is a slow decay that begins within months of deployment. The first year is usually the most deceptive period. Metrics look acceptable because the business environment has not yet changed enough to expose the model. Teams that built the system move on to new projects. Monitoring becomes sporadic. Ownership becomes unclear.
This quiet form of AI project failure follows a predictable pattern: organisational decay, operational drift and trust collapse. The original team disperses. It takes institutional context with it, including known limitations, edge cases and operational quirks. Monitoring shifts from proactive to reactive. Data pipelines develop quality issues that go undetected. Users begin overriding predictions with their own judgment.
Manual processes return as workarounds. The system keeps running while becoming steadily less useful. Eventually someone asks why the expensive AI implementation is being ignored by the team it was built to serve. Organisations that inherit AI systems from a previous vendor often meet exactly this scenario, which is why a post-deployment assessment is a sensible first step after any handover.
The three stages of AI project failure
- Organisational decay: the builders leave, documentation is thin, and nobody remembers why certain design choices were made.
- Operational drift: inputs change, pipelines break silently, and nobody is watching the right signals.
- Trust collapse: users stop relying on the output, and the system becomes shelfware even though it still runs.
AI Model Drift: The Inevitable Decay
AI model drift is the natural consequence of deploying models in environments that change. Every model is trained on a snapshot of historical data. Once deployed, the world keeps moving. Customer behaviour shifts. Market conditions change. Product catalogues are updated. Regulations are revised. Data pipelines accumulate quality issues. As the gap between training data and live data widens, prediction quality degrades in ways that start subtle and then compound.
AI model drift takes two primary forms. Data drift occurs when the statistical properties of input features change, even if the relationship between features and outcomes stays the same. Concept drift occurs when that relationship itself changes. In that case the model's learned patterns no longer reflect the current reality of the problem. The general idea is well described in the overview of MLOps on Wikipedia, which treats monitoring and retraining as core lifecycle steps.
Both forms of drift produce the same symptom: predictions become less reliable without any obvious infrastructure error. Our team treats AI model drift as a certainty rather than a possibility. Automated drift detection and retraining triggers belong in every production deployment from the outset. Treating drift as an edge case is one of the fastest routes to AI project failure.
MLOps Monitoring: Detecting Problems Before Users Do
MLOps monitoring is the practice of tracking AI system health in production with the same discipline applied to any critical infrastructure. Without it, AI model drift accumulates silently. With it, drift is detected early, when remediation is cheap and user impact is minimal. Google's reference on MLOps continuous delivery and automation pipelines describes this as moving from manual releases to automated, monitored pipelines.
Effective MLOps monitoring tracks a layered set of metrics. Data quality metrics watch the input pipeline for missing values, schema changes, distribution shifts and anomalous feature values. Model performance metrics track accuracy, precision, recall and business-relevant KPIs against ground truth labels as they arrive after deployment.
Feature distribution metrics detect AI model drift by comparing current inputs against the training baseline. Common statistical tests include the Population Stability Index and the Kolmogorov-Smirnov test. Infrastructure metrics cover latency, throughput, error rates and resource use. Combined, these layers provide the earliest signal of conditions that lead to AI project failure. They let the team intervene before users notice anything.
How to set useful alert thresholds
- Start from the business tolerance for error, not from a generic accuracy number.
- Set a warning level and a critical level for each metric, so alerts are graded.
- Route every alert to a named person, not a shared inbox.
- Review thresholds after each retraining cycle, because baselines move.
Post-Deployment AI: Ownership and Accountability
Almost every AI project failure investigation finds an ownership vacuum somewhere. When nobody holds clear accountability after launch, the maintenance work that prevents failure falls through organisational gaps. Alerts go unanswered. Retraining gets deferred. Data quality issues pile up. The post-deployment AI system becomes an orphan: technically running, operationally neglected.
Effective post-deployment AI governance assigns a named owner with explicit authority before the system goes live. Waiting until problems appear is too late.
The owner is accountable for monitoring outcomes and initiating retraining when thresholds are breached. They manage data quality issues and report system health to business stakeholders. They also coordinate model updates through the deployment pipeline. This single point of accountability prevents the diffusion of responsibility at the root of many AI project failure cases. Our team recommends documenting ownership and escalation procedures in the handover package before any post-deployment AI system moves from the delivery team to the operations team.
AI Governance: Designing for Sustained Operation
AI governance after deployment is not a compliance exercise. It is the operational framework that keeps a system trustworthy and valuable across its lifetime. The NIST AI Risk Management Framework makes the same point: governance is continuous, not a one-off gate. Four components are required for sustained post-deployment AI operation: retraining policies, performance thresholds, explainability standards and bias monitoring.
Retraining policies define when and how the model is updated. They specify the thresholds that trigger a retraining cycle and the process for collecting and labelling new data. They set the validation a retrained model must pass before replacing the current one. They also define the rollback procedure if the new model underperforms.
Performance thresholds define the minimum acceptable accuracy, precision, recall or business-KPI levels for autonomous operation. Below them, human review is required before outputs are used. Explainability standards document which inputs drive decisions, in a form that satisfies internal audit and external regulators. Bias monitoring checks outputs for systematic disparities across demographic or operational segments. ICANIO treats these four AI governance components as a foundation layer, not an afterthought, because missing governance is a quiet driver of AI project failure.
Post-Deployment AI: Key Metrics to Track
| Category | What to measure | Why it matters |
|---|---|---|
| Model performance | Accuracy, precision, recall vs baseline | Shows drift impact on quality |
| Data quality | Missing values, schema changes | Early pipeline warning |
| Business KPIs | Decision accuracy, error costs | Links model health to outcomes |
| User adoption | Override rates, manual fallback | Leading sign of trust collapse |
| Infrastructure | Latency, throughput, errors | Operational reliability |
AI Project Failure Modes: A Field Guide
Six recurring failure modes account for many of the problems teams meet in production. Recognising these AI project failure modes during design, rather than during incident response, is the most cost-effective way to prevent AI project failure. Each mode below comes with a practical fix.
1. Training-serving skew
The data used to train the model differs in format, distribution or quality from the data it receives in production. This is one of the most common causes of AI model drift right after launch, before the environment has even changed. The training pipeline used cleaned, normalised, validated data. The production pipeline feeds raw operational data with all its inconsistencies. The model performs well in evaluation and poorly in production.
Fix: share one feature pipeline between training and serving, and compare training and live feature distributions from day one.
2. Label shift
The definition of the correct output changes after deployment, without a matching retraining cycle. A fraud model trained on last year's patterns will miss this year's variants. A demand forecast trained on pre-disruption supply chains will mislead after a disruption. Label shift is a form of concept drift.
Fix: track prediction distributions against ground truth labels, so MLOps monitoring detects the shift within weeks rather than months.
3. Pipeline brittleness
The data pipeline lacks resilience to upstream changes. A source system is updated, a schema changes or a supplier feed disappears. A brittle pipeline then produces silently degraded inputs instead of visible errors. The model keeps running on corrupted data and produces plausible but wrong outputs.
Fix: add schema validation and data quality alerts at every pipeline stage. Good data engineering and DevOps practice treat a failed check as a stop signal, not a warning to ignore.
4. Undocumented business rule changes
The system was designed around business rules that later changed. Nobody updated it because the rules were implicit. Pricing models, eligibility criteria and compliance thresholds change regularly. A model optimised for old objectives becomes misaligned with new ones.
Fix: keep AI governance documentation that maps model assumptions to current business rules, and trigger a model review whenever a mapped rule changes.
5. Evaluation metric misalignment
The metrics used during development do not reflect the outcomes that matter in production. A model with high overall accuracy on a test set can still fail badly on the subset of cases where errors are most costly. Evaluation that rewards aggregate accuracy produces models that pass technical review but fail operational needs.
Fix: define business-aligned evaluation criteria, including critical subgroups, before training begins. Our guide to LLM evaluation before deployment covers how to automate that gate.
6. Lack of fallback
The system has no graceful degradation path. When confidence drops or data quality makes predictions unreliable, there is no route to human judgment or a simpler rule-based fallback. Users who meet unreliable outputs with no alternative start ignoring the system entirely. That is the final stage before abandonment and full AI project failure.
Fix: build confidence-based fallback paths and human review queues. Our article on human in the loop AI explains how to design those escalation points.
How to Prevent AI Project Failure: A Practical Checklist
Preventing AI project failure is cheaper than recovering from it. The checklist below turns the ideas above into concrete launch criteria. Our team recommends treating each item as a go-live requirement rather than a nice-to-have.
- Name a single post-deployment AI owner and document their authority.
- Instrument MLOps monitoring for data, model, business and infrastructure metrics.
- Record the training baseline so AI model drift can be measured.
- Write a retraining policy with triggers, validation steps and rollback.
- Define performance thresholds that route outputs to human review.
- Add a confidence-based fallback path for low-certainty predictions.
- Schedule a quarterly AI governance review with business stakeholders.
Automation helps here. Retraining pipelines, drift tests and deployment checks can run in the same CI/CD tooling teams already use for software development. Microsoft's guidance on model management and deployment in Azure Machine Learning shows how registries, versioning and monitoring fit together in a cloud platform.
Why AI Project Failure Is Also a Change Management Problem
Technical controls are only half of the answer to AI project failure. Many cases of AI project failure trace back to how people work with the system. If users do not understand what the model does, they will not trust it. If they cannot flag a bad prediction easily, problems stay hidden. If leadership measures the project only at launch, nobody funds the maintenance that follows.
A few habits make a large difference. Give users a simple way to report wrong outputs. Share a short monthly health summary with business owners. Celebrate retraining cycles as maintenance, not as admissions of failure. Budget for post-deployment AI work from the start, just as you would for any other production system.
For a broader view of the causes that appear before launch, such as unclear objectives or weak data foundations, read our companion guide on AI project failure causes and prevention. Together, the two articles cover the full lifecycle of risk.
Conclusion
AI project failure after launch is predictable, and that makes it preventable. Drift will happen, and so will the conditions for AI project failure. Pipelines will change. People will move on. The organisations that keep AI valuable are the ones that plan for these facts before go-live.
To avoid AI project failure, combine strong MLOps monitoring, a named owner, clear AI governance and practical fallbacks to turn a fragile demo into a durable system. None of these steps is exotic. They are the same operational disciplines that keep any critical software healthy.
If you are planning a new AI system, or inheriting one that has started to drift, our team can help you assess its health and design the monitoring and governance it needs. Contact ICANIO to start the conversation.
References
- NIST AI Risk Management Framework
- MLOps overview, Wikipedia
- Google Cloud: MLOps continuous delivery and automation pipelines
- Microsoft Learn: Model management and deployment in Azure Machine Learning
Frequently asked questions
Why does AI project failure happen after a successful launch?
AI project failure after launch is usually caused by AI model drift, unclear ownership, weak MLOps monitoring and missing retraining or governance policies. The system keeps running while the world around it changes. Without monitoring and maintenance to detect that change, prediction quality erodes until the system loses the trust of the people it was built to serve.
What is AI model drift and how is it detected?
AI model drift is the drop in performance that occurs when live data diverges from training data. Data drift means input statistics change. Concept drift means the relationship between inputs and correct outputs changes. MLOps monitoring detects drift by comparing current input and output distributions against training baselines with statistical tests, and alerts when drift crosses defined thresholds.
What does an MLOps monitoring program include?
An MLOps monitoring program tracks data quality, model performance, feature distributions for drift detection, business KPIs and infrastructure health. Alerts fire when a metric crosses a threshold, so the system owner can investigate before users are affected. It is the mechanism that makes post-deployment AI management proactive rather than reactive, and it is a key defence against AI project failure.
Who should own an AI system after deployment?
A single named owner with explicit authority should hold post-deployment AI accountability, rather than a shared committee. This person monitors outcomes, triggers retraining, manages data quality issues and reports governance metrics to business stakeholders. Ownership and escalation procedures should be documented before the system goes live, so responsibility never falls into an organisational gap.
What AI governance structures prevent post-launch failure?
Four AI governance components help prevent AI project failure: retraining policies that define when models are updated, performance thresholds that route outputs to human review, explainability standards that document what drives decisions, and bias monitoring that checks for systematic disparities. These structures should be designed before launch rather than retrofitted after problems appear in production.
How often should a production model be retrained?
There is no universal schedule for avoiding AI project failure. The right cadence depends on how fast the underlying data changes and how costly errors are. Many teams combine a regular review cycle with event-driven retraining that fires when drift or performance thresholds are breached. The retraining policy should state both triggers clearly, along with validation and rollback steps.
What are the early warning signs of AI project failure?
Early warning signs include rising user override rates, a return to manual workarounds, growing gaps between predictions and ground truth, unexplained shifts in input distributions and alerts that nobody owns. Any one of these signals of AI project failure is worth investigating. Several together usually mean the system is already in the quiet decay stage and needs an assessment.