Structured logging is one of the simplest changes a team can make to turn a fragile system into one it can actually operate. Building software that works in development is only the starting point. Running it reliably under real traffic, scaling it without losing visibility and recovering from failures without hours of guesswork is a different challenge.
That gap is bridged by observability. Specifically, it is bridged by structured logging, well-designed monitoring and the discipline to treat visibility as a first-class requirement. Teams that invest in it early tend to respond to incidents faster and deploy with more confidence than teams that bolt monitoring on after problems appear.
Our DevOps and cloud engineering team builds logging pipelines, application monitoring and log management platforms for enterprise systems. This guide covers what structured logging gives you that plain text cannot, how to monitor with the four golden signals, how log infrastructure scales and how to build a production observability strategy that works during real incidents.
Key Takeaways
- Structured logging writes events as named fields, usually JSON, so machines can query, filter and alert on them.
- Correlation IDs in every log entry let you reconstruct a request's path across microservices.
- The four golden signals (latency, traffic, errors, saturation) are the practical starting point for application monitoring.
- Log management at scale needs a designed pipeline: collection, buffering, processing, storage and retention.
- Alerts must be actionable, or engineers learn to ignore them.
- Over-logging, missing correlation IDs and unalerted metrics are the most common observability gaps.
What Makes a System Production-Ready?
A production-ready system is not simply one that passes tests. It can be monitored when behaviour is unexpected. It can be debugged quickly when failures occur. It scales without losing visibility and recovers from partial failures without cascading into full outages.
Structured logging and metrics are the foundation of each of these properties. Without them, teams lack the data to understand what the system is doing. Every incident becomes guesswork rather than diagnosis.
Observability is not a single tool. It combines logs, metrics, distributed tracing and alerting into a complete picture of system behaviour. Investing in this before launch is usually far cheaper than investing after the first major incident.
What Is Structured Logging?
Structured logging is the practice of writing log messages in a machine-readable format, typically JSON or key-value pairs. Each piece of information is a named field rather than text buried in a sentence. The difference is between text that humans must read and data that machines can query, aggregate and alert on.
A plain-text entry might read: "User login failed for user 12345 at 14:32:01." The structured equivalent is a JSON object with separate fields. It holds timestamp, level, service, event type, user ID and outcome, each searchable on its own.
{"ts":"2026-10-11T14:32:01Z","level":"warn","service":"auth","event":"login_failed","user_id":"12345","trace_id":"4bf92f35"}
During an incident, structured logging lets a team find every login failure for one user across all services in a time window within seconds. The same search across plain text needs brittle regular expressions. Those break whenever someone changes the message wording.
Why Correlation IDs Matter
Structured logging matters most in distributed systems, where one request may touch many services. Add a correlation ID as a standard field in every entry. Generate it at the entry point and pass it to every downstream call. Then the full path of any request can be rebuilt from log data alone.
The W3C Trace Context standard defines how to propagate these IDs over HTTP. OpenTelemetry builds on it, linking logs to traces automatically. Without consistent IDs, debugging a distributed failure means searching several systems at once and guessing time windows.
Seven Structured Logging Best Practices
Effective structured logging needs discipline beyond simply outputting JSON. Our team recommends these seven practices as a baseline for every service:
- Use one shared schema with standard field names across all services.
- Apply log levels correctly and consistently.
- Include a correlation or trace ID in every entry.
- Never log secrets or personal data.
- Log meaningful events, not every internal step.
- Use UTC timestamps in ISO 8601 format.
- Sample high-volume informational events in production.
Use Log Levels Correctly
Use DEBUG for development detail and INFO for normal operational events. WARN covers unexpected but recoverable situations, and ERROR is for failures needing attention. When everything is logged at ERROR, operators cannot separate real alerts from noise. This is one of the most common failures in teams new to structured logging.
For teams moving from a monolith to microservices, agree a company-wide logging standard before migration starts. That prevents the inconsistent formats that make log management painful later.
Protect Sensitive Data in Structured Logging
Sensitive data must never appear in logs, whatever the level. Passwords, tokens, payment card data and personal information must be masked or excluded before the message is written. Regulations such as GDPR make this a legal concern as well as a security one.
The OWASP Logging Cheat Sheet lists what to log, what to exclude and how to protect log data. It is a practical checklist for any application monitoring design.
Log What Matters
Focus on business-critical events, state transitions, errors and security-relevant actions. In structured logging, over-logging raises cost and buries the signals that matter during incidents. Sampling high-frequency informational events keeps volume under control without losing patterns.
Application Monitoring and the Four Golden Signals
Application monitoring provides the quantitative view that structured logging cannot. Logs capture individual events. Metrics aggregate behaviour into trends and anomalies that can be spotted before users notice.
Google's Site Reliability Engineering book defines the four golden signals as the most important metrics for a user-facing system. The framework remains a practical starting point in 2026. The table below summarizes them.
| Signal | What it measures | Example metric |
|---|---|---|
| Latency | Time to serve requests | p50, p95, p99 response time |
| Traffic | Demand on the system | Requests per second |
| Errors | Rate of failed requests | HTTP 5xx ratio |
| Saturation | How full resources are | CPU, memory, pool usage |
The Four Golden Signals Explained
Each of the four golden signals serves a different diagnostic purpose. Effective application monitoring tracks all four rather than only the most convenient.
Latency
Latency measures how long the system takes to respond. Track it as percentiles rather than averages. The p50 reflects the typical experience, while p95 and p99 show the slowest requests. A healthy p50 with a poor p99 is a tail latency problem that averages hide. Track failed requests separately, since fast errors can make latency look better than it is.
Traffic
Traffic measures the volume of requests the system handles. A sudden spike may need a scaling response. A sudden drop is equally important. It can signal upstream failures, DNS problems or load balancer mistakes that are not yet producing visible errors.
Errors
Errors measure the rate at which requests fail. This includes explicit failures such as HTTP 5xx responses and implicit ones, such as wrong results returned with a success code. For ecommerce and financial platforms, fast error-rate alerting is a requirement rather than a nice-to-have.
Saturation
Saturation measures how close critical resources are to their limits. Think CPU, memory, disk I/O, database connections and thread pools. As saturation nears its limit, performance degrades in ways the other signals may not show until the situation is severe.
Log Management for Structured Logging at Scale
Log management covers collection, transport, storage, indexing, querying, retention and archival of log data. At small scale, an agent on each server forwarding to one destination is enough. Across large distributed systems, log management becomes an infrastructure problem that needs design.
Widely used platforms include the ELK Stack (Elasticsearch, Logstash, Kibana), Grafana Loki, Datadog, Splunk and AWS CloudWatch Logs. The right choice depends on your cloud setup, team skills, query volume and retention needs. Loki is often chosen for cost-effective storage of structured logging output. Splunk and Datadog are common where advanced security analytics and dashboards are required.
The Log Pipeline
An enterprise log pipeline usually has four layers:
- Collection agents on each service instance or node.
- A buffer such as Apache Kafka or AWS Kinesis for reliability at high throughput.
- A processing layer for enrichment, parsing and filtering.
- Storage and indexing tuned to the team's query patterns.
Where data residency rules apply, the pipeline must route data only through compliant storage. Design for those rules from the start rather than retrofitting them. NIST SP 800-92 offers useful guidance on log management planning, retention and protection.
Building a Production Observability Strategy
A production observability strategy brings structured logging, metrics and log management together into one capability. The goal is not to collect as much data as possible. It is to collect the right data, keep it accessible and turn it into action through alerts and dashboards.
Make Alerts Actionable
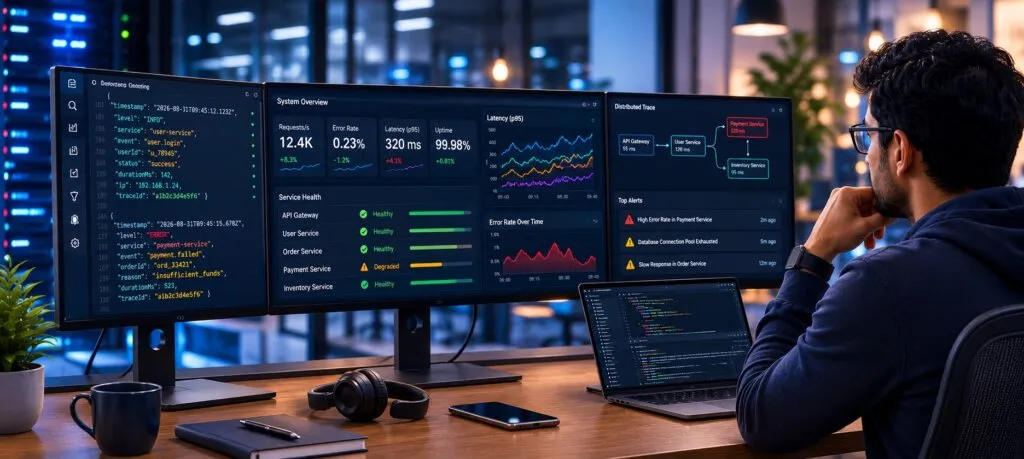
Structured logging feeds alerts, but metrics usually trigger them. Alerting is the most critical part of any observability programme. Dashboards nobody watches do not prevent outages. Every critical application monitoring metric needs an alert that reaches the right team through the right channel. That might be an on-call pager, a chat channel or email for low urgency.
Alerts must say what is wrong, which service is affected and what to check first. Vague, noisy alerts train engineers to ignore them. That turns observability spending into wasted infrastructure.
Correlate Metrics and Logs
The real power comes from connecting metrics and structured logging during an incident. A typical workflow looks like this:
- A metrics alert detects the issue.
- Dashboards narrow the scope to an endpoint or region.
- Structured logs are filtered by service, time window and level.
- Correlation IDs trace one failing request across every service.
- The team identifies where the failure began and fixes it.
This workflow is only possible when the observability foundation is built correctly. When it is, diagnosis is far faster than searching unstructured text. Our DevOps observability platform case study shows how these pieces fit together in practice.
Common Observability Mistakes to Avoid
Logging too much is as damaging as logging too little. Over-logging raises log management costs, makes queries slower and can add performance overhead under load. Log meaningful events, and sample high-frequency ones.
Missing correlation IDs in structured logging is the most common mistake in distributed systems. Without them, debugging means searching several log systems with hand-built time filters. Make ID propagation a standard in every service.
Metrics without alerts are the third common gap. Dashboards that need a human watching them do not give early warning. In our team's experience, these three issues explain most of the observability gaps found during initial reviews.
The Observability Maturity Curve
Most teams follow a similar path toward production observability. The stages below describe it in simple terms.
| Stage | Typical state | Next step |
|---|---|---|
| 1. Reactive | Basic error logs | Centralize logs |
| 2. Centralized | Shared storage, dashboards | Adopt structured logging |
| 3. Standardized | Schema and correlation IDs | Add actionable alerts |
| 4. Proactive | Alerts and runbooks | Regular trend reviews |
Moving between stages depends less on tooling than on discipline and shared standards. We start every structured logging engagement with an honest assessment of the current stage. Then we agree a plan and measurable goals for reaching the next one. Automation, such as logging libraries with the schema built in, makes the standard easy to follow.
Structured Logging Beyond Web Services
Structured logging is not only for web APIs. The same principles apply to batch jobs, data engineering pipelines, IoT gateways and machine learning services. Each has its own events worth capturing.
For data pipelines, structured logging should record job IDs, input and output row counts, schema versions and durations. For IoT gateways, include device IDs, firmware versions and connectivity events. For machine learning services, log model version, feature set version, latency and prediction confidence, while leaving out the raw personal inputs.
Using one structured logging schema across all of these makes cross-system questions easy. Which model version served the slow requests? Which pipeline run produced the bad data? With consistent fields, those become simple queries rather than investigations. That consistency is a core part of mature software development practice.
How ICANIO Builds Observability
ICANIO designs observability as part of our DevOps and cloud engineering services. Work typically covers logging standards, pipelines, dashboards, alert runbooks and on-call readiness. Our support engineering services then keep those systems healthy over time.
Observability also connects to other reliability work. Our guide to 502 Bad Gateway errors with Nginx shows how good logs speed up a common failure investigation. For database-heavy systems, logging retries and deadlocks alongside the SQL Server ACID guide principles makes concurrency issues visible.
Conclusion
Structured logging turns logs from text into data, and that single change makes every other observability practice possible. Combine it with the four golden signals, a designed log management pipeline and actionable alerts, and incidents become diagnosis rather than guesswork.
Start with a shared schema and correlation IDs, then add alerts and runbooks. Grow maturity one stage at a time.
If you want help designing or reviewing your observability stack, contact ICANIO and our team will be glad to talk it through.
References
- Observability (software), Wikipedia
- OpenTelemetry: Logs
- W3C Trace Context
- OWASP Logging Cheat Sheet
- Google SRE Book: Monitoring Distributed Systems
- NIST SP 800-92: Guide to Computer Security Log Management
Frequently asked questions
What is structured logging and why does it matter?
Structured logging writes log messages in a machine-readable format such as JSON, where each piece of information is a named field. Unlike plain text, these entries can be queried, filtered and alerted on by log management platforms without fragile parsing. It is essential in distributed systems because it enables fast, precise diagnosis across many services at once.
What are the four golden signals in application monitoring?
The four golden signals are latency, traffic, errors and saturation. Latency is how fast requests are served, traffic is request volume, errors is the failure rate and saturation is how close resources are to their limits. Tracking all four gives teams the coverage needed to detect and diagnose problems before they become user-visible outages.
What is the difference between logs and metrics?
Logs are detailed records of individual events, used for debugging and root cause analysis. Metrics are aggregated numbers tracked over time, used to spot trends and anomalies. Both are needed for production observability. Metrics tell you something is wrong, while structured logging gives the detailed context to find out what happened and why.
How does log management scale for enterprise systems?
Enterprise log management needs a designed pipeline covering collection, buffering, processing, indexing and storage. Tools such as the ELK Stack, Grafana Loki, Datadog and Splunk handle structured logging at scale. The right platform depends on your cloud infrastructure, compliance needs, query volume and retention policy. Data residency rules should be addressed at the design stage.
What is production observability?
Production observability is the ability to understand a system's internal state from its external outputs. It combines structured logging, application monitoring metrics, distributed tracing and alerting into one operational framework. Strong observability shortens incident resolution, improves deployment confidence and provides the data needed for proactive performance management and capacity planning.
Should structured logs include personal data?
No. Personal data, passwords, tokens and payment details should be excluded or masked before logs are written. Logs are often copied to many systems and retained for long periods, which multiplies exposure. Use allow-lists of safe fields, automated redaction in logging libraries and access controls on log stores, following guidance such as the OWASP Logging Cheat Sheet.