Three days before release. Four hundred test cases in the backlog. Time to run one hundred and fifty. Risk-based testing exists for exactly this moment. Most QA teams default to a familiar approach: test what has always been tested, test what is new, and test as far as time allows. It feels structured, but it is not strategic. In fast-moving development environments, that gap often decides whether a release goes smoothly or ends in a production incident. Risk-based testing (RBT) solves the problem by making test allocation deliberate and defensible rather than sequential and hopeful.
ICANIO's Application Development practice builds these programs and QA testing strategy frameworks for enterprise clients across the USA, UK, Germany, Australia, and Malaysia. The work covers test case prioritization methodology, exploratory testing integration, software testing strategy design, and release risk governance. This piece explains what risk-based testing means, how to run it across a sprint, the techniques that make it work, and the failure modes to avoid.
Key Takeaways
- Risk-based testing ranks test effort by the likelihood and impact of failure, not by raw coverage.
- Three pillars drive it: identify risk, assess risk, and prioritize test cases.
- Five techniques make it practical: risk workshops, change-impact analysis, failure mode mapping, weighted prioritization, and defect history.
- Documenting residual risk turns judgment calls into an auditable software testing strategy.
- A single sprint is enough to start, as long as predictions are compared with real defects afterwards.
What Is Risk-Based Testing?
Risk-based testing is a QA testing strategy for prioritising testing effort according to where the probability and impact of failure are highest. The approach is well established in testing literature, and the risk-based testing entry on Wikipedia summarises its origins. Rather than treating every test case as equally important, it requires deliberate decisions. What do we test first? What do we test thoroughly? What can safely receive less attention given time and resource constraints?
Why does this matter? Because time is always the scarcest testing resource. Releases rarely slip to make room for more testing. Risk-based testing accepts that reality and makes the trade-offs explicit, instead of letting the calendar make them silently.
Coverage-Driven Testing vs Risk-Based Testing
Risk-based testing differs from standard coverage-driven testing, where success is measured by the percentage of requirements, code paths, or features touched. Coverage metrics are useful in a software testing strategy, but they are blind to consequence. A 95% pass rate sounds reassuring. It stops being reassuring when the 5% that failed included a payment processing module.
| Dimension | Coverage-Driven Testing | Risk-Based Testing |
|---|---|---|
| Primary question | How much have we tested? | Have we tested the right things? |
| Allocation basis | Feature completeness, code coverage | Probability and impact of failure |
| Prioritization | Sequential or by feature area | Risk matrix: likelihood × impact |
| Time pressure | Run as many cases as possible | Highest-risk areas covered first |
| Defensibility | We covered X% of requirements | Highest risks covered; residual risk documented |
| Business alignment | Moderate; assumes equal value | High; reflects business consequence |
The Three Pillars of Risk-Based Testing
Implementing risk-based testing well comes down to three repeatable activities at the start of every release cycle. These pillars form the core of any effective software testing strategy built on risk principles.
Identify Risk
Risk identification in a software testing context is broader than most teams expect. It must cover the inputs that make exploratory testing effective: recent change history, coupling analysis, and business consequence data.
Risk does not come only from complex code. It comes from unclear requirements, third-party dependencies, recent code changes, rarely tested areas, and business domains where errors have real consequences. Good identification needs input beyond the QA team. Product owners know which features customers rely on most. Developers know which parts of the codebase are fragile. Support teams know what breaks in the field. A 30-minute risk workshop that brings these groups together produces a more reliable risk signal than any single team could alone.
Assess Risk: Likelihood and Impact
Once risks are identified, each is evaluated on two axes. Likelihood is how probable it is that an area will fail. Recently refactored code carries a higher likelihood than stable, untouched modules. Areas with complex logic, high coupling, or known fragility score higher.
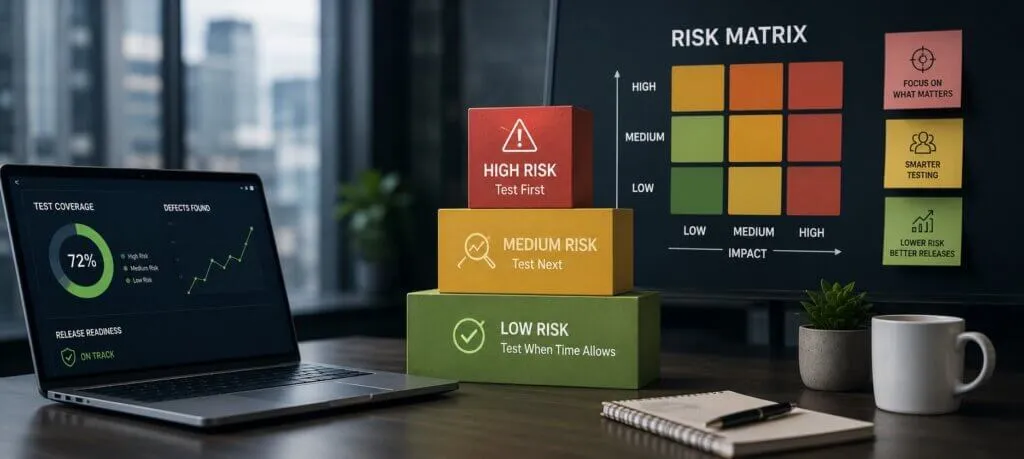
Impact is what happens if failure occurs. A broken checkout flow is higher impact than a misaligned label in an admin panel that three people use. Some teams formalise this as a risk matrix, assigning numeric scores and multiplying likelihood by impact to produce a risk priority number. Others keep it qualitative. Either way, the goal is the same: get the team aligned on what matters most before testing begins. The general idea mirrors how the NIST glossary defines risk assessment: identifying, estimating, and prioritising risks.
Test Case Prioritization
Test case prioritization is where the strategy becomes action. Highest-risk areas receive the most rigorous attention through functional, boundary, exploratory, and performance testing. Medium-risk areas receive standard coverage. Low-risk areas may receive smoke tests only, or nothing beyond automated regression in a constrained release.
Crucially, these decisions are documented. When something slips through, the team can explain the trade-off and learn from it rather than simply being surprised.
| Risk Level | Testing Approach | Coverage Depth |
|---|---|---|
| Critical | Functional, boundary, exploratory, performance, security | Full coverage with regression automation |
| High | Functional, exploratory, regression | Deep, documented coverage |
| Medium | Standard functional, automated regression | Structured but not exhaustive |
| Low | Smoke tests, automated regression only | Minimal; residual risk documented |
How to Run Risk-Based Testing in Five Techniques
Understanding the theory is one thing. Making risk-based testing operational in the next sprint is another. Five techniques make the approach practical at team level, and each one feeds exploratory testing with a sharper brief.
1. Risk Workshops Before Sprint Planning
A structured risk workshop at the start of each release cycle brings together developers, product managers, and QA. Each group names what concerns it most:
- Developers flag recent refactors or high-coupling code changes.
- Product managers flag features with high user visibility or external commitments.
- QA flags integration points with a history of failures.
- Support engineers flag recurring customer-reported issues.
This short conversation produces a shared risk register. That register drives the entire software testing strategy for the release, replacing gut-feel allocation with documented, cross-functional risk intelligence.
2. Change-Impact Analysis
One of the most reliable predictors of where defects will appear is where code has changed. Before each release, QA reviews the diff with developers. Together they work out what else those changes might affect. In codebases with high coupling, a change to one service can break components that look unrelated on the surface.
Change-impact analysis surfaces these dependencies explicitly. Exploratory testing effort then flows to the highest-probability failure areas rather than the most visible ones. In our team's experience, it is the most dependable way to brief an exploratory testing session. Teams running continuous testing in CI/CD pipelines can automate part of this mapping.
3. Failure Mode Mapping
For critical user journeys such as checkout, authentication, and data export, walk through each step. Ask what could break here, and what would happen if it did. This surfaces risk in user-facing workflows that a requirements document alone would miss.
The technique is borrowed from Failure Mode and Effects Analysis (FMEA), long used in engineering and manufacturing. It is especially good at finding edge cases and boundary conditions that standard functional test cases skip. ICANIO QA engineers use failure mode mapping during sprint planning for enterprise clients in the USA and Australia. The output is a set of exploratory testing charters grounded in consequence rather than feature completeness.
4. Weighted Test Case Prioritization
When an existing test suite must run in a constrained window, sort test cases by risk level and run the highest-risk tests first. If time runs out, the most consequential areas are already covered. Many test management tools, including Zephyr, TestRail, and Xray, support custom fields and sorting for test case prioritization by risk level.
Over time, this weighting becomes part of the test suite metadata rather than a per-sprint decision. That embeds risk-based testing in the ongoing QA testing strategy instead of treating it as a special-case activity.
5. Historical Defect Data
Where have bugs appeared before? A reporting module that caused three production incidents last year deserves extra attention, whether or not it changed this release. Past failure patterns are among the best predictors of future failure.
For enterprise clients in Malaysia and Germany maintaining multi-year systems, ICANIO adds historical defect analysis to the risk assessment process. This keeps well-known fragile areas from being under-tested simply because they did not change in a given sprint.
Risk-Based Testing in Agile and DevOps Delivery
Risk-based testing fits naturally into agile and DevOps workflows. It does not need a separate phase. The risk workshop becomes part of sprint planning. Change-impact analysis happens during code review. The risk register updates whenever requirements shift.
In DevOps pipelines, risk levels can map directly to quality gates. Critical-risk areas might block a deployment on any failed test. Low-risk areas might only raise a warning. This keeps fast delivery safe without slowing every release to the pace of the riskiest component. Cloud migrations and infrastructure changes deserve their own entries in the register, because configuration changes break things just as code changes do.
Security deserves explicit attention too. Areas handling authentication, payments, or personal data should rarely score low on impact. The OWASP Web Security Testing Guide is a useful checklist when scoring security risk. Our guide to security testing for QA teams covers this in more depth.
Benefits of Risk-Based Testing for QA Testing Strategy
Teams that adopt risk-based testing consistently describe three improvements. First, release confidence increases even when total test coverage decreases. The coverage that remains is concentrated where it matters. Leadership can see which risks were tested and which residual risks were accepted and documented. That is a more defensible outcome of test case prioritization than a coverage percentage that says nothing about business consequence.
Second, QA testing strategy becomes a cross-functional discipline rather than a siloed activity. When risk workshops bring product, engineering, and QA together, quality becomes a shared conversation rather than a hand-off. Developers learn which of their changes carry the highest testing burden. Product managers learn which acceptance criteria carry the most release risk. QA gains the context to direct exploratory testing intelligently instead of running scripted cases in isolation.
Third, the team builds an improving risk register over time. Each sprint, predicted risks are compared with the defects actually found, and the method improves. This feedback loop is how good QA teams become great ones. They do not run more tests. They get better at predicting where failure is most likely. ICANIO structures adoption programs for enterprise clients in the UK, USA, and Australia to include this retrospective risk calibration as a standard sprint activity.
Where Risk-Based Testing Fails: Common Mistakes
Risk-based testing has its own failure modes, and naming them plainly keeps adoption from stalling.
Scoring Familiar Areas as Low Risk
The most common mistake is scoring familiar areas as lower risk simply because the team is comfortable with them. Comfort is not evidence of stability. A good risk assessment uses objective evidence: recent change history, coupling, and defect data. Instinct is a starting point, not a verdict.
ICANIO facilitates risk workshops for enterprise clients in Germany and Malaysia precisely because a structured external perspective surfaces the blind spots internal teams tend to miss. A QA testing strategy built on incomplete risk identification has false confidence baked into its foundations.
Treating Risk Assessment as a One-Time Activity
Risk must be reassessed every release cycle. Requirements change, code is refactored, and an area that was low-risk in sprint five may be high-risk in sprint twelve after an architectural change. A risk register that is not updated becomes a false confidence generator. It undermines the whole software testing strategy and produces test case prioritization that no longer reflects real release risk.
Failing to Document Residual Risk
Suppose the team accepts that a low-risk area will get smoke tests only, and that area then fails in production. The debrief is very different when the trade-off was documented and approved than when it was implicit. Documenting accepted risk is not bureaucracy. It is what turns risk-based testing from a subjective call into an auditable software testing strategy that leadership can review and improve.
Adopting Risk-Based Testing in One Sprint
Teams that have not yet adopted risk-based testing do not need to overhaul their entire process. One sprint is enough to start. Follow these steps:
- Before testing begins, spend 30 minutes as a cross-functional team.
- Ask two questions: where is failure most likely, and where would it hurt most?
- Let the answers decide how testing time is allocated.
- Record the risk register, even informally.
- After release, compare predictions with the defects actually found, then adjust the weighting.
That feedback loop, repeated over time, is how teams improve their risk assessment accuracy. The result is a software testing strategy that reflects the real risk profile of the codebase and the business. ICANIO works with enterprise clients in the USA, UK, and Australia to formalise this process. Informal sprint conversations become documented, tool-supported QA testing strategy programs, with risk registers kept across releases and prediction accuracy tracked as a team quality metric.
Deciding which tests to automate? See our comparison of manual vs automation testing.
Conclusion
Risk-based testing replaces "test everything we can" with "test what matters most, and say so." It rests on three pillars: identifying risk, assessing likelihood and impact, and prioritising test cases accordingly. Five practical techniques make it work in real sprints. None of them requires new tools, only better conversations and better records.
The payoff compounds. Each release sharpens the risk register, each retrospective improves prediction accuracy, and each documented trade-off makes the QA testing strategy easier to defend. Our team recommends starting with a single sprint and a simple spreadsheet, then formalising once the habit sticks.
If you want help designing a risk-based testing program for your software development teams, explore our application development services or contact ICANIO to talk it through.
References
- Risk-based testing (Wikipedia)
- Failure mode and effects analysis (Wikipedia)
- Exploratory testing (Wikipedia)
- Risk matrix (Wikipedia)
- Risk assessment, NIST CSRC glossary
- OWASP Web Security Testing Guide
- ISTQB, International Software Testing Qualifications Board
Frequently Asked Questions
Does risk-based testing mean ignoring low-risk areas entirely?
No. Low-risk areas typically receive smoke tests and automated regression coverage. Risk-based testing redirects effort; it does not eliminate it. The goal is to concentrate constrained testing time where the business consequence of failure is highest, not to skip areas entirely. Residual risk in lower-priority areas is documented and accepted rather than simply ignored, so everyone understands the trade-off.
Who should be involved in the risk assessment?
Risk assessment should be cross-functional. Product owners contribute user impact context. Developers contribute technical fragility assessment. Support teams contribute field failure history. QA contributes historical defect data and testing experience. A risk assessment produced only by the QA team misses the business consequence dimension that product and customer insight provides, which weakens the whole exercise.
How often should risk assessments be updated?
Risk must be reassessed every release cycle. A common failure mode is treating risk assessment as a one-time activity that stays static across sprints. As code is refactored, requirements shift, and new dependencies arrive, the risk profile of each area changes. A risk register that is not updated generates false confidence and quietly misdirects testing effort.
What is the difference between likelihood and impact?
Likelihood is the probability that an area will fail, often driven by recent code changes, high coupling, or complex refactoring. Impact is the consequence of that failure, such as a broken checkout flow versus a minor UI misalignment in an admin panel. Risk-based testing prioritises areas where both are high, with documented trade-offs where only one is elevated.
How does risk-based testing fit into agile sprint workflows?
Risk-based testing integrates naturally into agile delivery. The risk workshop runs at the start of each sprint and sets the test case prioritization basis for that cycle. Change-impact analysis runs after the development diff is reviewed. The risk register is updated as requirements evolve, so the QA testing strategy keeps pace with delivery instead of going stale.
How does exploratory testing relate to risk-based testing?
Exploratory testing is one of the main tools risk-based testing uses for high-risk areas. Instead of following fixed scripts, testers investigate a risky area with a clear charter and time box. The risk register tells them where to explore and what failure would cost. Scripted tests confirm known behaviour, while exploratory sessions find the unknown problems scripts miss.