DATA ENGINEERING · AWS DATA LAKE · FINTECH AUTOMATION
Icanio built a data lake integration platform for a wealth management technology partner, automating the extraction of 50+ Wealth Spectrum data views into a secure, scalable AWS data lake.
Quick Answer
What Is a Data Lake Integration Platform for Financial Data?
A data lake integration platform automates the extraction of financial data from source systems into a centralized, queryable AWS data lake without altering the original records. ICANIO built this data lake integration platform to automate 50+ Wealth Spectrum data views into AWS S3 and MySQL, orchestrated by Apache Airflow and made instantly queryable through AWS Glue and Amazon Athena, all with zero manipulation of source data.
Executive Summary
Turning Manual Wealth Data Extraction Into an Automated Pipeline
Financial teams required a secure and scalable way to automatically extract raw data from multiple Wealth Spectrum views while preserving data integrity and enabling seamless querying within cloud-based analytics infrastructure. ICANIO’s partner was facing exactly that gap: manual data extraction that slowed financial data processing workflows, a lack of automation that limited scalability across multiple data views, the critical requirement to ensure zero manipulation of source financial data, and limited integration with cloud analytics tools that delayed insights.
ICANIO addressed this by building a Data Lake Integration Platform rather than another manual export process. The objective was to automate extraction of 50+ Wealth Spectrum data views, store raw data in AWS S3 and MySQL without transformation, orchestrate scheduling and monitoring through Apache Airflow, catalog datasets for discovery with AWS Glue, and enable fast querying directly from the data lake through Amazon Athena, all validated through comprehensive testing and UAT before deployment.
The result was 50+ automated pipelines replacing manual extraction, zero manipulation of raw source data, and dramatically faster insights through Athena query acceleration, all running on reliable, scalable, cloud-native infrastructure.
“A finance team does not trust a data lake because it is fast, it trusts a data lake because every number in it traces back to the source untouched.”
The Challenge
Five Barriers to Scalable Financial Data Extraction
Financial teams required a secure and scalable way to automatically extract raw data from multiple Wealth Spectrum views while preserving data integrity and enabling seamless querying within cloud-based analytics infrastructure.
The Data Lake Integration Platform Gap
Manual data extraction slowed financial data processing workflows, leaving teams waiting on exports that should have run automatically.
Automation Gaps Before This Data Lake Integration Platform
A lack of automation limited scalability across multiple data views, so adding new views meant adding new manual effort.
Zero Manipulation Was Non-Negotiable
Ensuring zero manipulation of source financial data was critical, since any transformation risked breaking the trust financial teams placed in the numbers.
Why This Data Lake Integration Platform Was Needed
Limited integration with cloud analytics tools delayed insights, leaving valuable data extracted but not actually usable for analysis.
Scale Needs Before This Data Lake Integration Platform
Complex datasets required reliable scheduling and monitoring pipelines, and growing analytics needs demanded infrastructure that could scale with them.
Data Lake Integration Platform Solutions Provided
A Six-Part Data Lake Integration Platform
Icanio Technologies developed automated Python-based data pipelines to extract Wealth Spectrum data views, securely store them in AWS infrastructure, and enable efficient querying through integrated analytics services. The solutions included:
Automated Extraction of 50+ Data Views
Automated extraction of 50+ Wealth Spectrum data views replaced manual exports with a repeatable, scheduled process that runs the entire Wealth Spectrum data pipeline automatically every day.
This Data Lake Integration Platform Stores Raw Data
Raw data is stored in AWS S3 and MySQL without transformation, preserving the integrity of the original source records.
Apache Airflow Orchestration
Apache Airflow orchestrates scheduling, execution, and monitoring workflows, giving the team visibility into every pipeline run.
AWS Glue Data Cataloging
AWS Glue catalogs datasets for seamless data discovery, so analysts can find and understand available data without manual documentation.
Amazon Athena Querying
Amazon Athena enables fast querying directly from the data lake, letting analysts run SQL queries without provisioning a database.
Testing This Data Lake Integration Platform
Comprehensive testing and UAT ensured reliable deployment, validating every pipeline before it touched production financial data.
Business Outcomes
Measurable Results Across Automation, Integrity, and Scale
This data lake integration platform delivered outcomes across every dimension of the team’s original data extraction bottleneck, converting a manual, unscalable process into an automated, trustworthy, and query-ready data lake.
50+Pipelines
Automated data ingestion
Zero Manipulation
Raw data integrity
Faster Insights
Athena query acceleration
Reliable Workflows
Automated job scheduling
Scalable Architecture
Cloud-native infrastructure
Key learnings
What This Engagement Proves for Financial Data Pipelines
Zero Manipulation Builds Trust in This Data Lake Integration Platform
Storing raw data in AWS S3 and MySQL without transformation wasn’t just a technical choice, it was what let financial teams trust that every number in the data lake traced back to the original Wealth Spectrum source.
Orchestration Is What Makes 50+ Pipelines Manageable
Automating extraction alone would not have scaled to 50+ data views without a way to schedule, monitor, and recover failed runs. Apache Airflow orchestration is what turned a large pipeline count from a maintenance burden into a manageable system.
This Data Lake Integration Platform Unifies Cataloging
Automated ingestion means little if analysts cannot find or query the data afterward. Pairing AWS Glue cataloging with Amazon Athena querying is what turned the data lake into something teams actually used, not just a storage destination.
Conclusion
From Manual Wealth Data Exports to an Automated Data Lake
Manual extraction of Wealth Spectrum data views might have been workable for a handful of reports, but for a financial team scaling analytics across dozens of data views, it had become a real constraint on speed and trust. This engagement demonstrates that a single data lake integration platform can resolve automation, integrity, and query-speed gaps within one structured programme rather than three separate initiatives.
By automating extraction of 50+ Wealth Spectrum data views, orchestrating pipelines with Apache Airflow, cataloging datasets with AWS Glue, and enabling fast querying through Amazon Athena, ICANIO helped this partner achieve zero manipulation of source data and dramatically faster insights. The automated scheduling, data cataloging, and cloud-native infrastructure delivered through this engagement are the foundation every future Wealth Spectrum data view this team adds will run on.
Related Resources
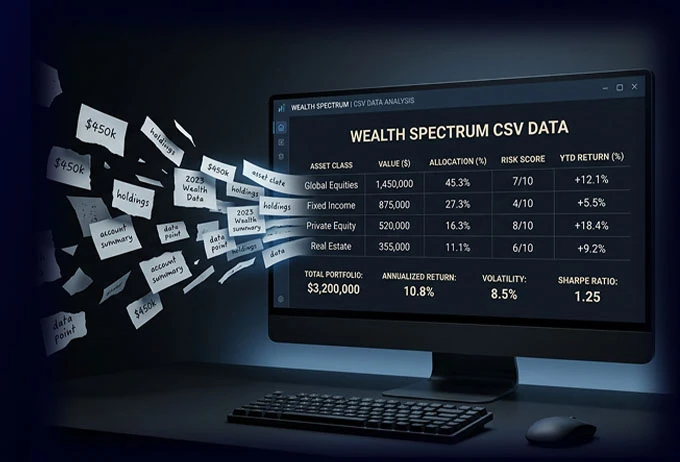
Our team delivers data engineering like this through ICANIO's data and artificial intelligence services. Cloud pipelines and their automation also draw on DevOps and cloud engineering. Related work for fintech and banking teams includes a Wealth Spectrum CSV parser platform. To plan a similar data lake integration platform, contact ICANIO.
- Data and Artificial Intelligence Services
- Fintech and Banking Industry Solutions
- Wealth Spectrum CSV Parser Platform: 50% Faster
- Bank API Data Acquisition Portal: 50% Faster
- Top 5 Best Fintech App Development Wins
References
- Data lake: overview of the data lake storage model.
- Apache Airflow documentation: official Airflow orchestration docs.
- What is AWS Glue?: official AWS Glue guide.
- What is Amazon Athena?: official Athena query service guide.
- Amazon S3 user guide: official S3 storage docs.
Frequently asked questions
Common Questions About This Data Lake Integration Platform
Why does a data lake integration platform matter for financial data?
A data lake integration platform automates the extraction of financial data from source systems into a centralized, queryable data lake without altering the original records, which matters because financial teams need both scale and provable data integrity.
Why store raw data without any transformation?
Storing raw data in AWS S3 and MySQL without transformation ensures zero manipulation of source financial data, so every downstream analysis can be traced back to the original Wealth Spectrum records with full confidence.
What role does Apache Airflow play in this platform?
Apache Airflow orchestrates scheduling, execution, and monitoring for all 50+ automated pipelines, giving the team visibility and control over every extraction run instead of relying on manual scripts.
How does AWS Glue help teams find the right data?
AWS Glue catalogs datasets for seamless data discovery, so analysts can locate and understand available data without needing manual documentation or tribal knowledge.
Why use Amazon Athena instead of a traditional database for querying?
Amazon Athena enables fast querying directly from the data lake using standard SQL, without the team needing to provision or manage a separate database just to analyze the data.
How was reliability validated before this platform went live?
Comprehensive testing and UAT ensured reliable deployment, validating every pipeline against real Wealth Spectrum data before it touched production financial systems.